What peptide manufacturing automation is actually doing right now, unit operation by unit operation
SPPS automation commonly handles coupling, deprotection and washing, with cleavage generally occurring after chain assembly. Other platforms include solution-phase, ligation and hybrid processes; not all peptide automation is the same four-step cycle.
The pressure to automate is scale. Commercial demand for GLP-1 peptide APIs can reach tens or hundreds of kilograms annually and in some cases approach metric-ton production levels, with synthesis stages progressing from mg-to-g at discovery through kg at clinical and multi-kg campaigns at commercial scale (Bachem, 2026). At that volume, a typical 30-amino-acid peptide needs 30 sequential coupling and deprotection cycles, and at 99% efficiency per step the cumulative yield loss and impurity accumulation become significant, yielding dozens of closely related byproducts (Neuland Laboratories, 2026).
Synthesis, cleavage, purification and analytics may all be automated to different degrees. Their suitability depends on process understanding, उपकरणे, monitoring and validation rather than simply how often a step repeats.
Which peptide-manufacturing steps can be automated without weakening quality or regulatory accountability
The steps that can be automated are those where the instrument produces the evidence and the evidence is validated to a technology-neutral standard. Automated fast-flow synthesis achieves roughly 2.5 minutes per amino acid versus 26 minutes per amino acid for commercially available heated synthesizers at 70 degrees C, with residues incorporated in as little as 40 seconds at up to 90 degrees C (Hartrampf et al., Science, 2020). Parallel purification of 96 peptides takes 1.55 hours and 1 litre of solvent versus 56 hours and 50 litres for sequential RP-HPLC, a 36-fold time and 50-fold solvent reduction (Biotage brochure, vendor document V.6).
What makes these steps defensible is that the validation route does not change because a machine performs them. I Q2(R2) requires that an analytical procedure be fit for its intended purpose and that the validation package be justified by product, matrix, analyte and technology; it is technology-neutral and therefore applies to AI-assisted or automated peptide QC methods (I Q2(R2), final version, नोव्हेंबर 2023). ICH Q14’s enhanced development approach adds risk assessment of analytical procedure parameters, uni- or multivariate experiments or modelling, and a defined control strategy with set-points and ranges including method operable design regions (I Q14, final version, नोव्हेंबर 2023).
FDA’s computer software assurance guidance for production and quality-system software has a medical-device scope. Its risk-based ideas may be informative, but it does not automatically establish the requirements for pharmaceutical peptide manufacturing software.
की टेकअवे: automating a step and automating the decision about that step are different projects with different evidence burdens.
Which steps must stay under qualified human control, and why
Peptide Drug Development Recombinant Peptide Synthesis The EMA’s synthetic-peptide guideline makes the release decision the clearest human-owned step. Purity is one of the most important critical quality attributes for synthetic peptides; structure confirmation is required; counterion identity and content must be controlled with a justified upper limit; and a specification parameter merely labelled “high molecular weight impurities” is not acceptable, because dimers, trimers, oligomers and aggregates must be individually specified (EMA, in force 1 June 2026).
The FDA’s position on AI is still a draft. The January 2025 guidance on AI to support regulatory decision-making is labelled “Not for implementation. Contains non-binding recommendations” (FDA, 2025), and it proposes a risk-based credibility assessment framework in which credibility is trust established through credibility evidence for a particular context of use (Federal Register, docket FDA-2024-D-4689, 2025).
The chemistry itself explains why some decisions resist delegation. Aspartimide formation occurs during standard Fmoc deprotection with 20% piperidine in DMF, and the base pKa values behind that step are piperidine 11.1, HOBt 4.6 and the DBU conjugate acid 13.5 (Kong et al., 2025). Choosing a base is choosing a side-reaction profile, which is a qualified chemist’s judgement, not a software default.
Where peptide manufacturing automation currently fails: difficult sequences and milligram-to-kilogram scale-up
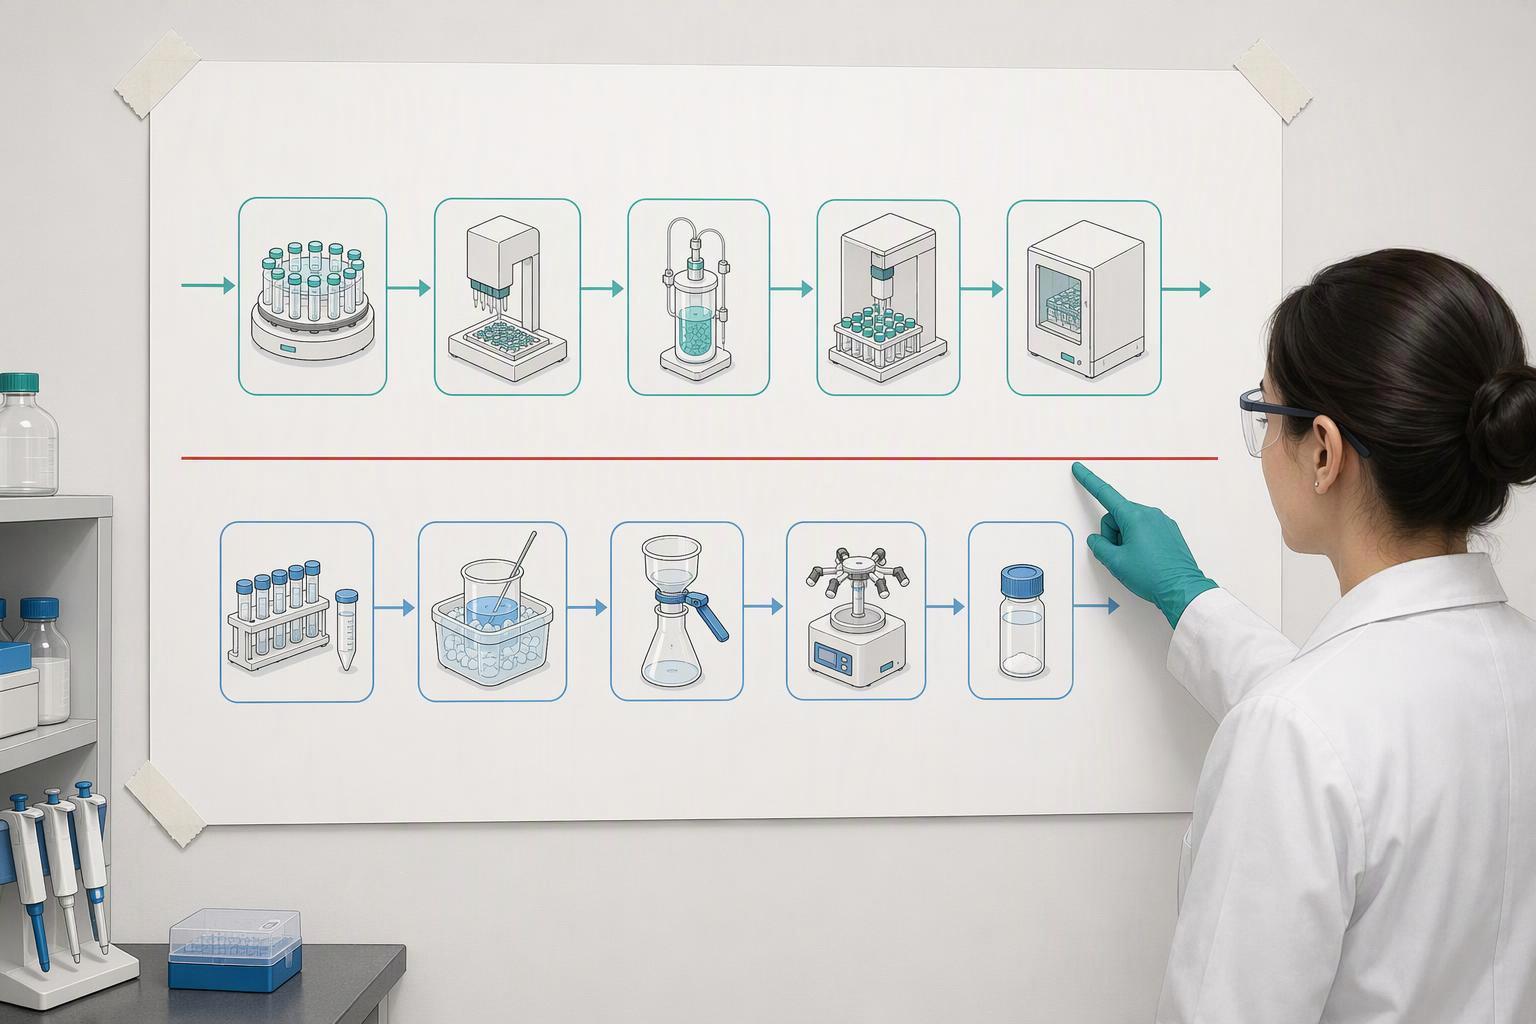
Difficult sequences above 50 करण्यासाठी 60 amino acids remain a challenge even with automated SPPS protocols, and no unique protocol exists for highly hydrophobic peptides: every new synthesis still needs special optimisation (Mueller et al., 2020). The mechanism is on-resin aggregation. Difficult sequences are defined as peptides poorly solvated while attached to the solid support, preventing complete deprotection and coupling steps, and they contain a high number of hydrophobic residues such as Leu, वॅल, Phe and Ile; Val and Ile are beta-branched, with glycine inducing beta-sheet packing in combination with these (Mueller et al., 2020).
Asp-X motifs can be susceptible to aspartimide formation depending on sequence and deprotection conditions. Select and validate a suitable method, whether executed manually or automatically. The next residue in a motif is not necessarily the C-terminal residue of the whole peptide.
The capability ceiling is visible in the published performance data. Isolated yields across automated fast-flow protein sequences were 2.2 करण्यासाठी 19.0 मिग्रॅ, किंवा 1 करण्यासाठी 5%, after HPLC purification, with proinsulin (86 aa) at 2.2 mg and HIV-1 protease (99 aa) at 5.3 मिग्रॅ, and the longest chain at 164 aa over 327 consecutive reactions (Hartrampf et al., Science, 2020). That is a research-scale result, not a manufacturing claim.
Scale-up is a separate discipline. Milligram screening measures chemical feasibility, not manufacturing robustness: at kilogram scale the process must be redesigned around reactor geometry, mixing and mass transfer, heat removal, resin behaviour, purification loading and impurity-profile shifts, so transfer is process re-engineering with pilot batches rather than protocol duplication (Global Biotech Laboratories, 2026). Capacity is also route-specific: SPSS, LPPS, hybrid convergent and recombinant-plus-synthetic architectures are not interchangeable, and purification rather than synthesis often sets the deliverable volume, so a site can be capable of building a molecule and unable to purify it at the required volume (CDMO Hub, 2026).
What records must cross-reference for a reviewer to defend an automated batch decision
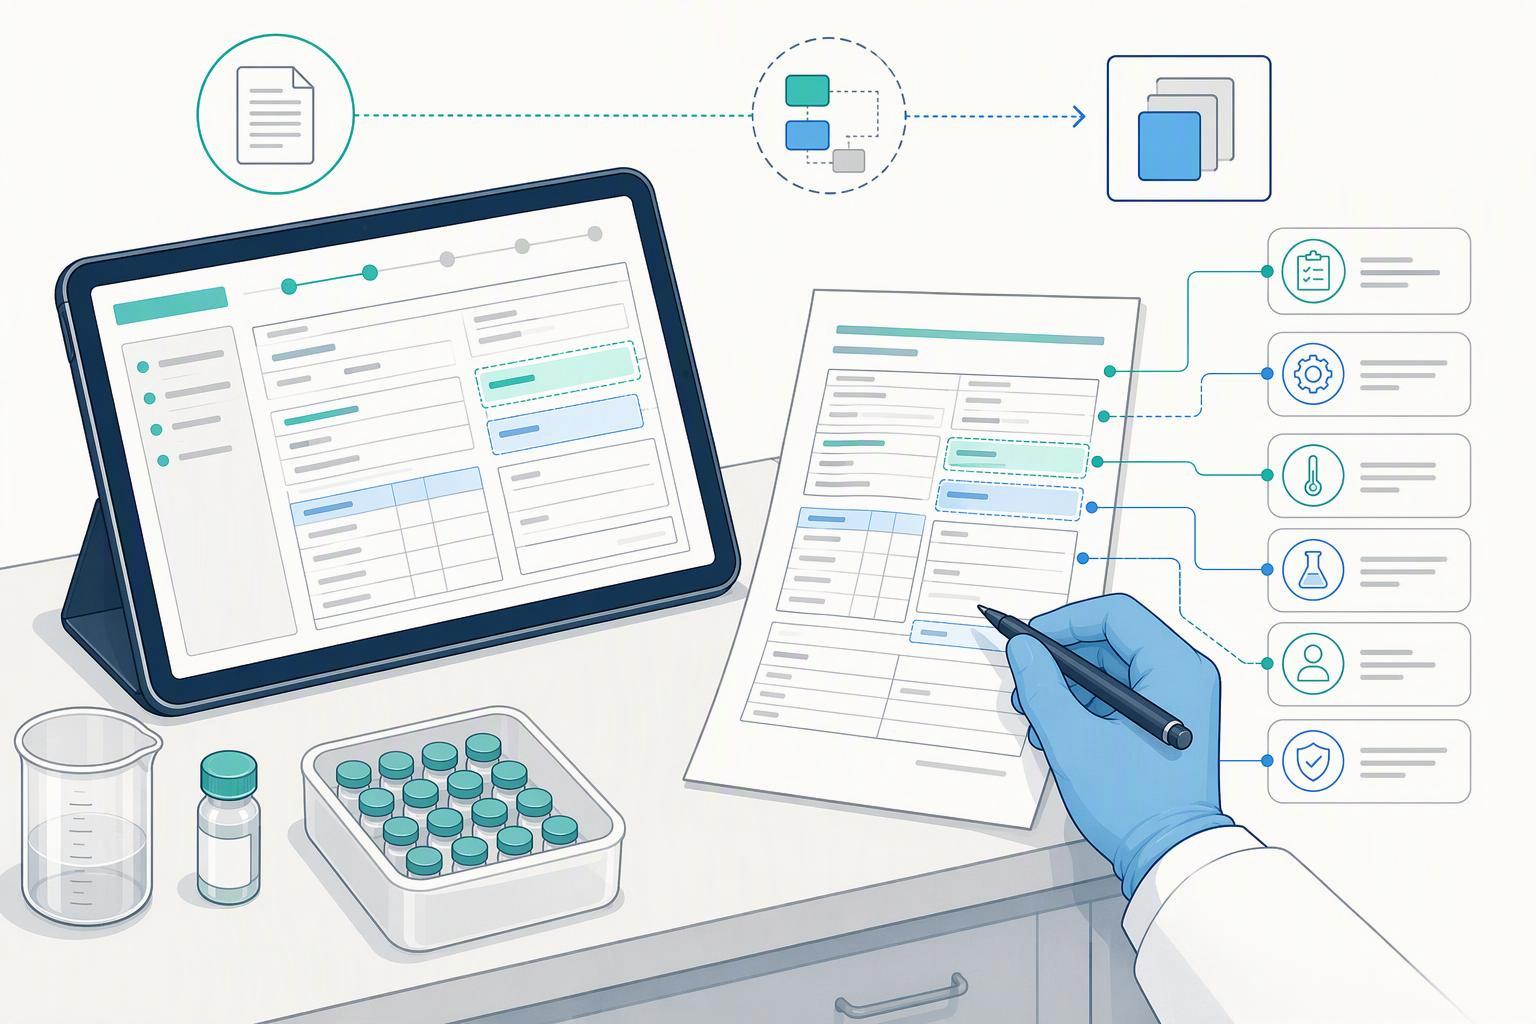
An automated batch decision is defensible when the record package lets a reviewer reconstruct what the system did and who authorised it. 21 CFR 11.10(a) requires validation of systems to ensure accuracy, reliability, consistent intended performance and the ability to discern invalid or altered records, आणि 11.10(e) Peptide P requires secure, computer-generated, time-stamped audit trails that do not obscure previously recorded information and are retained at least as long as the subject records (21 CFR Part 11, current as in force).
The signature layer must cross-reference the decision. Signed electronic records must show the printed name of the signer, the date and time of signature, and the meaning associated with the signature, such as review, approval, responsibility or authorship (21 CFR 11.50(a), current as in force). The MHRA’s Classical Peptide Synthesis ALCOA principles add that data must be attributable, सुवाच्य, समकालीन, मूळ आणि अचूक, with the “+” adding complete, सुसंगत, टिकाऊ आणि उपलब्ध, and there is no difference in expectations whichever acronym is used (MHRA, 2018).
The MHRA also sets the control expectation: organisations are expected to implement, design and operate a documented system providing an acceptable state of control based on the data integrity risk with supporting rationale, such as a data integrity risk assessment (MHRA, 2018). Routine forensic checking is not expected; periodic audits are (MHRA, 2018).
The peptide-specific layer comes from the EMA. During SPPS, standardised steps such as deprotection, washing, coupling and capping need not be described in detail each time provided conditions are given and it is clear where they are used; the final cleavage and deprotection step must be described in detail including scavengers; and material traceability from synthesis steps through the final active substance is expected (EMA, प्रभावी 1 June 2026).
What measured gains and risks peptide manufacturing automation actually delivers
Published fast-flow synthesis and purification demonstrations show gains under their stated conditions. Cross-publication cycle times, solvent intensities and scales are not necessarily head-to-head comparisons. Benchmark the same construct and acceptance criteria, including purification and recovery.
Solvent choice carries a measurable cost signal. The solvent cost per amino-acid coupling cycle runs from 151 EUR for DMSO/EtOAc (1:9) with recycling, करण्यासाठी 297 EUR for DMF, 406 EUR for NBP/EtOAc (1:1), आणि 431 EUR for DMSO/EtOAc without recycling (Green Chemistry review, 2022). Dna And Peptide Synthesis
Epimers can have identical mass; deletion products ordinarily differ by the mass of the missing residue. Both may challenge chromatographic selectivity, but they are not both generally near-isobaric to the intact peptide. Use diagnostic mass and separation evidence appropriate to the impurity.
What the sources do not provide is equally important. No retrieved source quantifies a peptide manufacturing failed-batch or out-of-specification rate, and none quantifies a release-testing turnaround time or a measured reduction from automated QC. Defect-rate reduction should be treated as qualitative and attributed to in-process analytics rather than claimed against an unmeasured baseline.
How should a peptide R&D team sequence its own automation rollout?
Sequence an automation rollout using the actual process risk, detectability, control strategy and validation needs. ICH Q9(R1), finalized in January 2023, provides a risk-management framework, not a mandatory order of automation projects. Pharmaceutical software controls must be assessed under the applicable framework. पेप्टाइड्स
Two boundary cases should be excluded from early automation. Difficult sequences above 50 करण्यासाठी 60 amino acids still need sequence-specific optimisation (Mueller et al., 2020), and milligram-to-kilogram transfer is process re-engineering rather than protocol duplication (Global Biotech Laboratories, 2026). Automating either before the process is understood simply automates the failure.
वारंवार विचारले जाणारे प्रश्न
Does the conventional automation case still hold for high-volume, well-behaved sequences?
होय, and that is where the case is strongest. Short, well-solvated sequences that run the same cycle hundreds of times are exactly the conditions under which automated peptide synthesis quality control pays for itself, because the coupling and deprotection steps are reproducible and the analytical endpoints are stable. The boundary only starts to move once a sequence is poorly solvated on the resin, since incomplete coupling and deprotection cannot be corrected by tighter scheduling. The conventional case is not wrong; it is narrower than the way it usually gets stated.
We already run an automated line. Can a human boundary be retrofitted?
Retrofitting review and control points may be feasible, but assess software, इन्स्ट्रुमेंटेशन, validation, data integrity and operational cost before choosing a change. Existing hardware does not necessarily capture all required evidence.
How should we respond to vendor ROI figures for AI in peptide manufacturing?
Treat them as unverified until you can see the method. There is currently no public benchmark set for AI-optimised purification across difficult sequences, so any headline return figure rests on a vendor’s own sequence mix, scale and analytical endpoints, and will not transfer to yours. Ask for the sample set, the sequence difficulty distribution, the scale, and the time window, and if those are not available, run the comparison on your own hardest sequences before committing.
Does the EMA’s 1 June 2026 effective date change what we document for standardised SPPS steps?
It changes the traceability expectation rather than the chemistry. EMA’s synthetic-peptide guideline became effective on 1 June 2026, and for standardised solid-phase steps it expects the documentation to show how each step was controlled and how the record connects synthesis through to the final active substance. If your automated steps already produce time-stamped, attributable records, the work is mostly mapping them to that expectation; if they do not, that gap is the priority under the requirements now in effect.
Why can’t a difficult sequence simply be handed to an automated synthesizer?
Difficult sequences can require changes in solvent, coupling, deprotection, तापमान, resin or assembly route. Length alone does not guarantee poor solvation, and appropriate automated process development may improve performance. Confirm the method experimentally at the intended scale.
निष्कर्ष
The evidence supports this split unevenly, and that is the honest position. Cycle-time and solvent gains are measured and large. Defect-rate and release-turnaround improvements are not quantified in any retrieved source, so they should not be claimed. Difficult sequences above 50 करण्यासाठी 60 amino acids and milligram-to-kilogram transfer remain human-led process development (Mueller et al., 2020; Global Biotech Laboratories, 2026).
The next step is a records audit, not a purchase order. Before the first automated batch, confirm that the system validation, ऑडिट ट्रेल, signature manifestation and traceability chain can be produced on demand, because those are the artefacts a reviewer will ask for first (21 CFR Part 11, current as in force; MHRA, 2018).