ደረጃ 1: Define What Your GLP-1R Binding Calculations Actually Predict
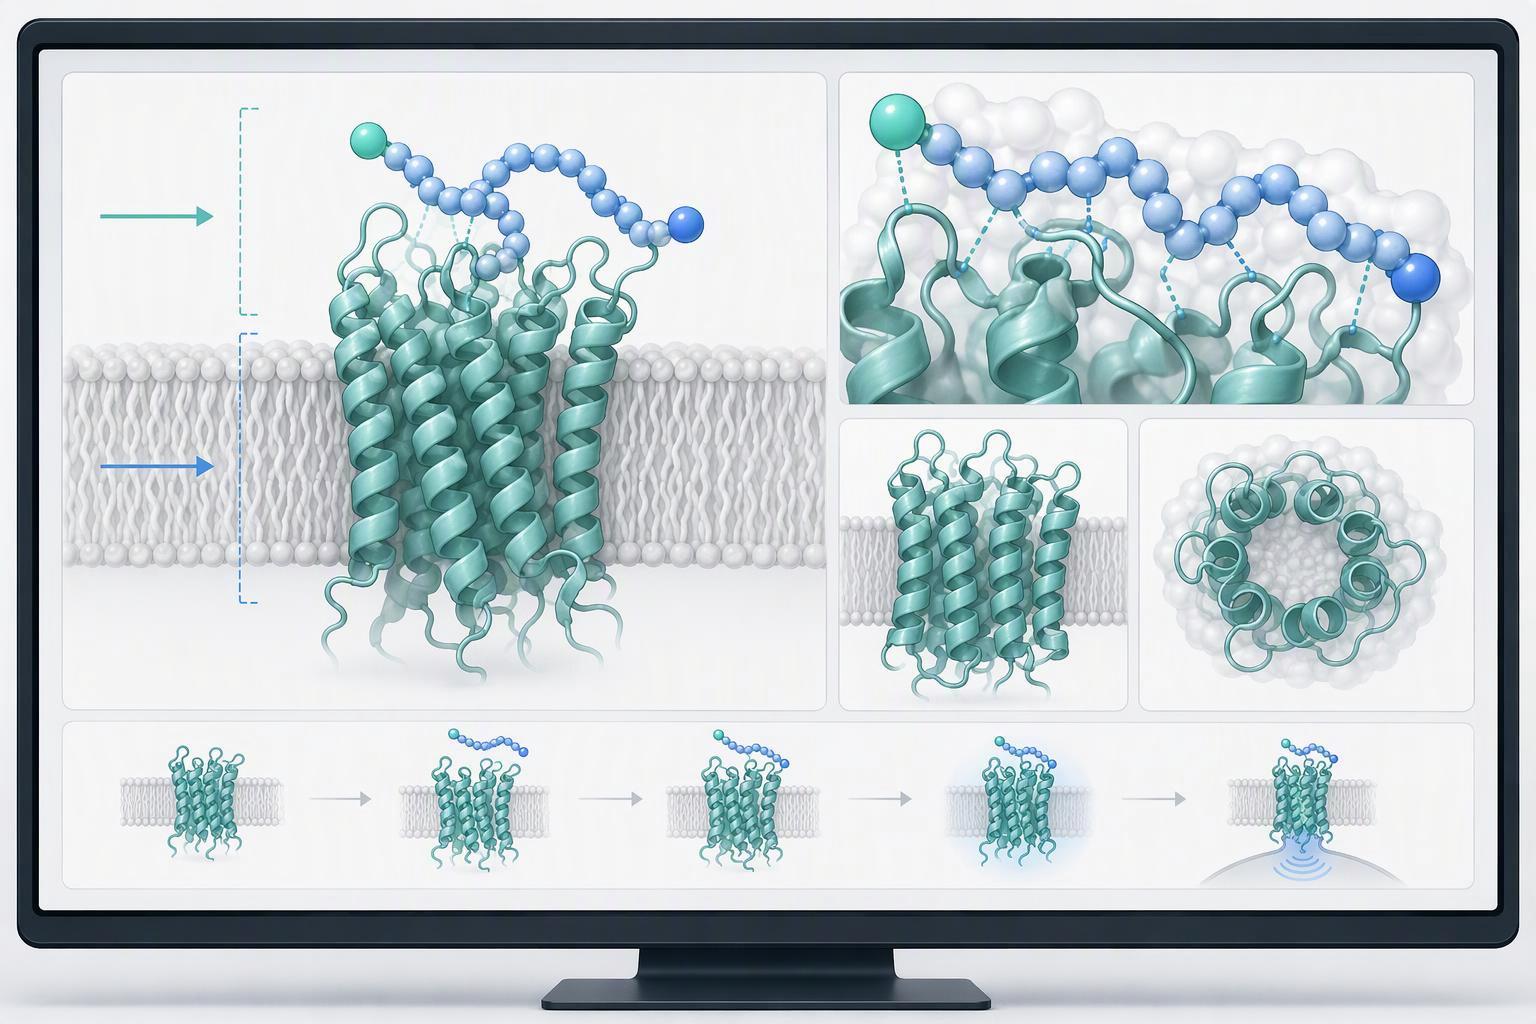
Three different numbers come out of a typical modeling run, and they do not mean the same thing. ሀ docking score is a scoring-function value for one pose of the peptide in one receptor structure; it ranks poses, it does not measure affinity. ሀ predicted Kd is that score pushed through a trained regression to look like a dissociation constant. ሀ free-energy estimate (MM-PBSA, MM-GBSA, alchemical FEP) is a physics-based calculation over an ensemble of frames, and it carries a standard deviation you should read as part of the number.
None of these is a measured binding constant.
The reason the spread is so wide for GLP-1R is structural. Class B1 GPCR peptide recognition is a two-domain problem: the peptide C-terminus engages the extracellular domain while the N-terminus must reach into the 7TM core for activation, so a single rigid receptor pose cannot represent the bound state, and docking is sensitive to which receptor state you modeled (የተፈጥሮ ግንኙነቶች, 2022).
That sensitivity is not academic. In a 2026 Frontiers in Pharmacology study, the same 18-residue agonist scored 55 nM against one receptor conformer and 360 nM against another (SR18; PRODIGY against the 0 ns conformer versus the MD central conformer). MM-PBSA over 1 μs of MD gave −98.79 ± 8.77 kcal/mol for SR18 against −167.22 ± 16.20 kcal/mol for GLP-1. No cell-based assay was run.
የመነሻ ቁልፍ: A score is a hypothesis with a confidence interval, ውጤት አይደለም. Before you rank anything, write down which receptor state, which method, and which error bar produced each number.
ደረጃ 2: Audit the Model Assumptions Before You Trust a Ranking
A ranking is only as good as the assumptions underneath it, and those assumptions are usually invisible in the output table. Before you act on a predicted order, ask three questions: what force field and sampling regime produced the pose, how long the simulation ran, and what the model was actually benchmarked against.
Sampling is the first place rankings break. Class B GPCR MD runs typically stabilize only after 200–500 ns, with continued relaxation for a further 1.5–2.5 μs, and many activation processes outlast conventional MD timescales altogether (Assessment of Conformational State Transitions of Class B GPCRs, 2019). ሀ 100 ns run that looks converged may simply not have sampled the relevant state.
Pose accuracy has a ceiling too. In a 2025 GPCR–peptide benchmark, AlphaFold2 reproduced correct binding modes in 94% of post-cutoff complexes (63/67), with interaction-classification AUC of 0.86 for AF2 versus 0.76 for Chai-1, while ESMFold and NeuralPLexer failed to enrich binders at all (GPCR–peptide binding classifier benchmark, 2025-04-26). Read that 94% as a single-source benchmark result, not a guarantee for your target.
|
Model class |
Reported performance |
Assumption most likely to break |
|---|---|---|
|
MD / free-energy |
Stabilizes after 200–500 ns |
Sampling is long enough |
|
AF2 / AF3 |
94% correct modes; AUC 0.86 / 0.82 |
Benchmark transfers to your peptide |
|
Chai-1, ESMFold, NeuralPLexer |
AUC 0.76; no binder enrichment |
Score tracks affinity |
The failure mode is documented: re-docking RMSDs of roughly 5–5.5 Å have been reported for ligands known to be active (GLP-1R structural determinants, 2016-04-08).
ደረጃ 3: Design a Minimal Variant Panel That Can Falsify the Prediction
A panel earns its cost when each variant can prove the ranking wrong. Size it to the model’s sensitivity, not to the synthesis budget: if the calculation claims to separate two variants, at least one member of the panel has to sit on that boundary.
Three groups do most of the work. Single-position substitutions at residues the model flags as contact points test whether those contacts carry the predicted weight. An N-terminal truncation or substitution series tests the region the model treats as decisive, and it is the group most often left out: the SR18 authors noted cell-signaling studies remained to be performed, so the N-terminal behavior their modeling implies is still an open question rather than a settled input. One modification class that changes chemistry rather than sequence, ስቴፕሊንግ, ቅባት ቅባት, or a D-amino acid scan, tests whether the prediction survives a change the sequence-based model was never trained on.
ብጁ የፔፕታይድ ውህደት Treat the result as discriminating variants, not a library. Every member should map to one assumption and one readout that would falsify it.
|
Variant class |
Assumption tested |
Falsifying readout |
|---|---|---|
|
Contact-point substitution |
Flagged residue drives affinity |
Shift in measured binding |
|
Synthetic Peptide Synthesis N-terminal series |
N-terminus dominates recognition |
Loss or retention Spps Solid Phase Peptide Synthesis of binding |
|
Chemistry-changing modification |
Sequence alone predicts behavior |
Divergence from predicted rank |
ደረጃ 4: Pair Every Binding Readout With a Functional One
A binding constant tells you how tightly a peptide occupies the receptor. It does not tell you how strongly that occupancy activates it. Receptor occupancy is the fraction of GLP-1R molecules with a peptide bound; cAMP accumulation is the downstream second-messenger readout that reports activation; biased agonism describes ligands that favor one signaling pathway over another, such as cAMP over β-arrestin-2 recruitment. Because these are separate measurements, a ranking built only on affinity can invert once you measure function.
Tirzepatide illustrates the gap. It binds GLP-1R with roughly 5-fold weaker affinity than native GLP-1 but is 20-fold less potent in cAMP accumulation, and in the presence of human serum albumin that potency shift reaches 81-fold while GLP-1(7-36) potency stays unaltered (JCI Insight, 2020). Potency and affinity are not interchangeable, and the assay medium changes the number.
Biased agonists widen the gap further. Native GLP-1 has a cAMP EC50 of 3 pM, መቃወም 29 pM for liraglutide and 343 pM for the biased dual agonist CT-859, which produces under 5% β-arrestin-2 recruitment versus 99% for GLP-1 (ፒኤምሲ, 2025). A predicted affinity gain that leaves cAMP flat is a different result from one that shifts it, and your panel has to distinguish the two.
Binding affinity, cAMP potency, pathway bias and model-classification AUC are different endpoints. Report the receptor system, assay conditions and comparator with each value; compare numerical potencies within a matched experiment. Counterion toxicity observations for another peptide do not establish a GLP-1R-specific threshold.
ለጠቃሚ ምክር: Run the functional assay in the same medium you plan to compare across, since the albumin-dependent potency shift above is a property of the assay conditions, not of the peptide alone.
ደረጃ 5: Treat Reference-Material Quality as a Variable in the Comparison
Your comparator is a measurement, and it carries its own error. Before a reference standard enters a GLP-1R comparison, confirm what it actually is. Counterion form is the most common hidden variable: the TFA salt of the tetra-branched peptide M33 showed 5–30% greater cytotoxicity toward normal bronchial epithelial cells than its acetate counterpart, and MOG formulated with TFA accelerated encephalomyelitis onset by roughly 5 days at comparable incidence and severity (The Effects of Counter-Ions on Peptide Structure, Activity, and Functionality, ባዮሞለኪውሎች, 2025). The mechanism is routine chemistry: Fmoc/tBu SPPS followed by RP-HPLC yields trifluoroacetate salts, with TFA either bonded to basic residues or adsorbed in the lyophilizate, and USP and EP treat the acetate anion in peptide drugs as an impurity whose level must be measured (The Role of Counter-Ions in Peptides, An Overview, ፋርማሲዩቲካልስ, 2020).
|
QC attribute |
What to verify |
Assay it can shift |
|---|---|---|
|
Purity by HPLC |
Reported method and integration threshold |
Potency, apparent affinity |
|
Counterion identity |
Acetate vs. ቲኤፍኤ, stated on the CoA |
Cell viability, functional readouts Artificial ሰው ሠራሽ ፖሊፔፕታይድ የፔፕታይድ ውህደት |
|
ቀሪ TFA |
Measured level, not assumed absent የ polypeptide ውህደት |
Cytotoxicity, proliferation assays |
|
Lot number |
Traceable to a single synthesis batch |
ብዙ-ወደ-እጣ ማነጻጸር |
ደረጃ 6: Reconcile the Disagreement and Set the Next Panel
When a measured affinity and a predicted ranking disagree, the first question is not which model to revise. It is whether the assay reached equilibrium. A worked GnRH receptor case shows how far this can go: ሀ 2 h incubation gave an apparent Kd of 200 pM while kinetic analysis gave 29 pM, because the radioligand dissociation half-time was 4 h and full equilibrium required at least 20 h (Ligand binding assays at equilibrium: validation and interpretation, Br J Pharmacol, 2010). The non-equilibrium read overestimated Kd roughly 7-fold, and the model was never the problem.
That single case also disposes of a common shortcut. The widely repeated “within two-fold” agreement criterion is not supported by that source, so it should not be used as the pass mark for GLP-1R binding calculations.
Localize the disagreement before you touch the model. If the gap traces to an incubation time, a buffer, or a reference lot, change the panel or the protocol. If it survives a clean equilibrium measurement and repeats across variants, change the model.
በተደጋጋሚ የሚጠየቁ ጥያቄዎች
Can a docking score replace a measured binding constant?
አይ. A docking score is an estimate produced by a scoring function, and the error of that estimate is not reported alongside it. A measured dissociation constant (Kd) is a fitted parameter with a confidence interval, which is what makes it usable as a comparison baseline.
The SR18 case shows why the distinction matters in practice. In that study, the same peptide scored differently against two receptor conformers, ሀ 55 nM result against one and 360 nM against another, and no cell-based assay was performed to adjudicate between them. A score that moves by nearly an order of magnitude with the starting structure is a hypothesis about binding, not a measurement of it. Use docking to rank candidates for synthesis, then let the assay decide.
Which assay format should I use for a GLP-1R comparison?
Choose on what the format actually reports. HTRF and Tag-lite competition assays give equilibrium affinity in a plate format and suit larger variant panels. Radioligand competition does the same with a different detection principle, and carries the handling overhead that comes with radioisotopes. SPR reports kinetics, association and dissociation rates, which tells you whether a potency difference comes from faster off-rate or slower on-rate.
That kinetic detail is the reason to pay for SPR on a shortlist rather than a full panel. One caution on published comparability: a competitor application note reports Kd values of 0.816 nM and 2.347 nM on two instruments with no error bars, replicates or n-numbers, so treat cross-instrument numbers as indicative until you reproduce them under your own conditions.
What if my reference standard’s lot changes mid-study?
Re-qualify the new lot against the old one in a single assay run before it enters the comparison. Run both lots side by side on the same plate, same day, same protocol, and record the potency ratio.
Check the certificate of analysis for purity, counterion and residual TFA, since any of these can shift apparent potency independently of the peptide sequence. If a potency shift tracks the lot change, treat it as a material effect on your comparison rather than as model error. A lot change is a variable you can control; a scoring function is not.
ማጠቃለያ
The loop is the method. Define what your GLP-1R binding calculations actually predict, audit the assumptions behind the ranking, design a variant panel that could falsify it, pair every binding readout with a functional one, control the comparator’s quality, and reconcile the disagreement before you order the next panel. None of those steps is optional, because a simulation becomes useful evidence only at the moment a measured readout can contradict it. Until then it is a hypothesis with a confident-looking table attached.
That is also why the comparator deserves the same scrutiny as the model. If your reference material varies lot to lot, the disagreement you are reconciling may belong to the standard rather than to the prediction. A documented reference-material and QC workflow supports that control: የትንታኔ የምስክር ወረቀት, purity and counterion data, and lot traceability recorded alongside the assay result, so the next comparison starts from a known baseline. It can be used to keep the measured side of the loop as auditable as the computational side.