What Expanded Genetic Codes for Custom Peptide Design Actually Change
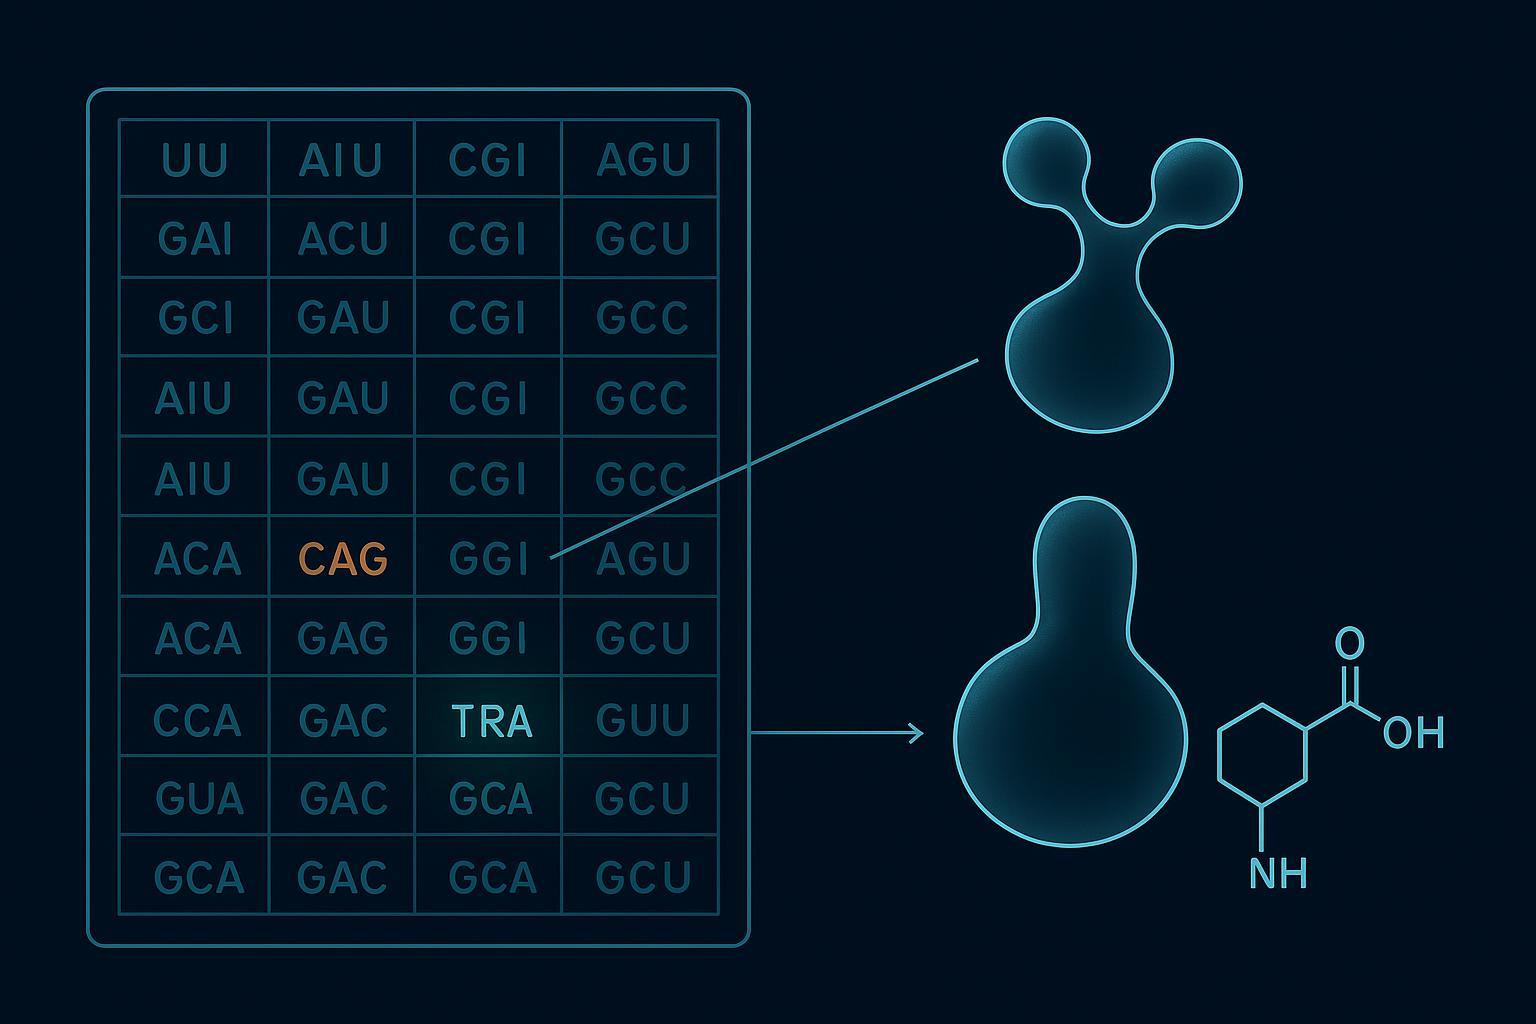
The standard genetic code assigns 64 codons: 61 sense codons and 3 stop codons, and each sense codon specifies one of the 20 canonical amino acids (Addgene Genetic Code Expansion collection, last reviewed 19 November 2025). An expanded genetic code rewrites that assignment. One or more codons are redirected to a noncanonical amino acid through codon reassignment, installed site-specifically by an orthogonal tRNA / aminoacyl-tRNA synthetase pair that charges only its own engineered tRNA and nothing else in the host.
That definition matters less than the failure mode it locks in. Amber (UAG) suppression reads through a stop codon, so it competes directly with release factor 1. When suppression loses that race, the result is premature termination and truncated product, a loss that recoded or RF1-knockout hosts are specifically designed to reduce (Nature Biotechnology, 11 September 2024). Sense-codon reassignment fails differently: the reassigned codon still competes with its original meaning, so the product arrives as a mixture containing canonical misincorporants rather than a short chain.
သော့ယူသွားပါ။: Amber suppression fails by truncation; sense-codon reassignment fails by mixture. Yield and purity therefore move independently, and the failure mode you inherit is set by the codon strategy you choose, not by how skilled the supplier is.
[DIAGRAM: labeled 64-codon table with UAG and one sense codon highlighted, each arrowed to its orthogonal tRNA/synthetase pair]
Why the Toolbox Moved Faster Than the Reviews
The reference material most teams reach for lags the chemistry. တစ် 2025 review puts the count at over 300 noncanonical amino acids successfully used in genetic code expansion (Nature Communications, 29 September 2025), while the most-cited review in search results on this topic dates to 2014. Plasmid-level resources have kept closer pace: Addgene’s expanding GCE collection lists roughly 150 synthetase plasmids and 26 bacterial strains, with content last reviewed on 19 November 2025 (Addgene). If your selection shortlist was built from a decade-old review, it is describing a smaller toolbox than the one that exists.
How Expanded Genetic Codes Reshape Noncanonical Amino Acid Selection
That same codon strategy also sets the terms of noncanonical amino acid selection, where pair choice, not residue choice, is the binding constraint. Four factors decide which tRNA-synthetase pair you can use: substrate fit, codon strategy, host organism, and whether you need to encode more than one ncAA at once. Work through them in that order and most of the apparent freedom in the residue catalog disappears.
Two platforms dominate. ဟိ Methanocaldococcus jannaschii TyrRS/tRNA^Tyr pair accepts tyrosine-like and aromatic side chains. The pyrrolysyl-tRNA synthetase scaffold and its evolved variants take lysine-like and bulky residues, and tolerate more structural variety. Note that RF1 knockout is a host strategy that raises suppression efficiency, not a third pair.
|
ဝန်ဆောင်မှုများ Feature |
M. jannaschii TyrRS/tRNA^Tyr |
PylRS/tRNA^Pyl variants |
|---|---|---|
|
Substrate scope |
Tyrosine-like, aromatic |
Lysine-like, bulky, structurally diverse |
|
Codon strategy |
Amber (UAG) suppression |
Amber, ochre, or sense-codon reassignment |
|
Host compatibility |
E. coli, yeast, mammalian cells |
E. coli, mammalian cells, cell-free systems |
|
Multiplexing suitability |
Limited; overlapping substrate tolerance |
Better suited to orthogonal pair expansion |
Multiplexing is where the field is moving. တစ် 2024 codon-compression strategy identified 12 mutually orthogonal tRNA-synthetase pairs compatible with the known GCE resource set, which matters if your design needs two or more distinct ncAAs in one chain.
Then there is the boundary between what a ribosome can install and what only SPPS can. Side-chain modifications on an α-amino-acid backbone are GCE-compatible. β-amino acids, α,α-disubstituted residues, depsipeptides, and many N-methylated residues are not; they are SPPS-only or in vitro-only. If your target residue sits on that list, no pair selection will rescue it.
Reading Suppression Efficiency Honestly
Suppression efficiency is a range, and the range only means something with the strain and reporter attached. Earlier systems delivered roughly 10–20% for a single amber codon. Optimized and evolved systems reach 50–117% depending on context, and 76–104% in the RF1-deleted C321 strain. Those figures describe different constructs, so they are not a ladder you can climb by picking the highest number.
Incorporation efficiency is also not the same metric as near-cognate readthrough. Readthrough runs about 1% in Top10, about 3% in BL21, and up to 17% in MG1655, reaching as high as 47.5% at a given amber site in an RF1-deleted background. One measures how much ncAA you install; the other measures how much wrong amino acid you install alongside it.
The practical consequence: a specification that names only a percentage, without naming the strain and the reporter, is not a specification. Ask for both before you accept an efficiency figure.
Designing Peptide Libraries with Noncanonical Amino Acids
Once the pair is fixed, the display platform you choose sets the ceiling on which noncanonical amino acids your library can contain at all. mRNA display and RaPID sit highest on ncAA tolerance because the whole cycle runs in vitro: flexizyme charges the tRNA directly, so the ribosome never has to compete with a host synthetase, and backbone-modified residues stay in play. Ribosome display ranks high but system-dependent, since tolerance shifts with the lysate and the release-factor setup. Phage display remains workable, because phage display can carry noncanonical residues via amber-encoding helper phage, though the host machinery constrains which residues survive. Yeast display is the most constrained of the four.
Position matters as much as platform. Position-wise versus global ncAA diversification split the design space: single or few defined sites suit a mechanistic probe or one conjugation handle and stay easy to characterize, while pervasive substitution suits stability or protease-resistance screens and is far harder to verify residue by residue.
Where Library Design Meets Route Selection
A library built around a backbone-modified residue cannot be produced by genetic code expansion at all, so the display decision and the production decision have to be made together rather than in sequence. The stability payoff is what makes that constraint worth accepting. In one inhibitor series, cyclic β2,3 residues pushed serum half-life past 168 hours at 37 °C in human serum, against 4.6 hours for the corresponding alanine variant; a second scaffold in the same work reached 48 hours versus ဆိုင် 4.2 နာရီ. N-methylation extended proteinase-K stability from 6 minutes to roughly 110 minutes in its own assay, and D-amino-acid substitutions moved half-life from minutes to hours in theirs. None of these figures generalizes to peptides as a class: each belongs to its own scaffold and assay. The practical consequence is narrow and firm. If your stability target requires a backbone modification, the route is chosen for you, and the library has to be designed inside that limit from the start.
Site-Specific Conjugation Strategies Enabled by Expanded Codes
That route decision carries straight into conjugation, where an ncAA handle buys positional control that no canonical residue can match, and it changes the failure mode rather than eliminating failure. A bioorthogonal handle installed at a defined position gives the highest positional control and the lowest off-target burden of any site-specific peptide conjugation strategy, but the failure you then manage is incomplete incorporation or unreacted starting material, not mis-targeting. Cysteine is chemoselective and cheap, yet over-alkylation, oxidation and disulfide scrambling are routine. Lysine coupling gives regioisomer mixtures. N-terminal chemistry improves on lysine but stays sequence- and context-dependent.
|
Chemistry |
Selectivity |
Kinetics |
Copper |
Failure mode it produces |
|---|---|---|---|---|
|
SPAAC (azide + cyclooctyne) |
High |
Moderate |
Not required |
Unreacted azide handle |
|
CuAAC (azide + alkyne) |
High |
Fast |
Required |
Copper-mediated side reactions |
|
Tetrazine-TCO |
Peptide ပေါင်းစပ်မှု High |
Fastest |
Not required |
Hydrolysed tetrazine |
|
Electrophilic ncAA cyclization |
High when geometry is preorganized |
Intramolecular |
Not required |
Competing intermolecular product |
The menu is short. SPAAC is copper-free and operationally simple; CuAAC is the most robust but copper sensitivity is the liability; tetrazine-TCO labels fastest; and electrophilic ncAA cyclization is intramolecular and clean when the geometry is preorganized, as reported for doubly bio-orthogonal ncAA handles (Nature Communications, 2023).
Choosing Between Bioorthogonal Conjugation and Native Chemical Ligation
Native chemical ligation and ncAA conjugation solve different problems and are not substitutes. NCL is the route when the target requires a backbone modification, a D-residue, or a segment that no orthogonal pair will charge; its prerequisite is a viable ligation junction and a thioester segment. ncAA conjugation is the route when the target is a standard α-backbone peptide that needs one defined attachment point, and its prerequisite is a pair whose substrate scope accepts the handle plus a host or extract that suppresses the competing canonical readthrough.
The practical consequence: make the conjugation decision at the same time as the ncAA decision. A handle the chosen pair will not charge is a redesign, not a substitution.
Analytical Controls That Prove Sequence Fidelity
Whatever conjugation route you settle on, the control package is what converts a synthesis claim into a defensible specification, and it has to be designed before the first lot is made, not assembled after a deviation. For any peptide carrying a noncanonical residue, sequence fidelity analytical controls rest on five elements: exact-mass confirmation of the intact peptide plus sequence-localizing fragment ions spanning the modified residue by LC-MS/MS; incorporation-efficiency quantitation, meaning the fraction of peptide bearing the ncAA versus canonical misincorporants or unlabeled product; a diastereomer/epimer control against a synthetic reference or an orthogonal chiral or retention-time method, because standard LC-MS often cannot distinguish epimers; orthogonal translation system validation with negative controls and no detectable off-target readthrough; and, for element-tagged ncAAs such as selenium or boron variants, amino acid analysis or ICP-MS (2026 review on precision bioconjugation and site-specific incorporation, retrieved 2026-02-04).
Setting Acceptance Criteria Before the First Lot
Each control becomes useful only when it carries a number. Tie mass accuracy to the residue being confirmed, tie the incorporation-efficiency threshold to the resolving power of the assay that measures it, and require the epimer control to name the reference standard it compares against. Where the peptide is a parenteral candidate, the pharmacopeial limit is dose-derived: USP <85> sets endotoxin limit = K/M, with K = 5 EU/kg/hour for non-intrathecal routes and K = 0.2 EU/kg/hour intrathecal, expressed per mg or per mL of the maximum human dose. ICH Q2(R2) sets the validation parameters, and the MHRA ALCOA principles frame the data integrity expectations around them.
A control that is not written into the specification before the first lot is a control you will be negotiating after a deviation.
Scale-Up: SPSS, CFPS and Lot-to-Lot Fidelity Risk
Those controls then have to survive scale-up, because the route that produced your research batch is not automatically the route that produces your clinical batch, and the fidelity risk profile changes with it. Solid-phase peptide synthesis operates at milligrams to grams per batch, with preparative and industrial workflows reaching tens to hundreds of grams, and some sequences into kilogram scale. Cell-free systems typically deliver mg per litre: about 96 ± 3 mg/L for a protein carrying 40 identical noncanonical amino acids, while an optimized RF1-deficient extract reached roughly 1,780 ± 30 mg/L for sfGFP (cell-free ncAA incorporation literature, 2020). The scale gulf between cell-free and solid-phase routes is real, and it shapes which fidelity risks dominate at each stage.
Two lot-to-lot risks follow from that split. Under amber suppression, truncation and readthrough products vary with host state, so the impurity profile can shift between fermentation runs even when the target band looks unchanged. Under sense-codon reassignment, the noncanonical-to-canonical ratio can drift while total yield stays flat, which means a yield-only release test will not catch it.
The practical consequence: the fidelity controls from the previous section belong in the release specification for every lot, not only in the qualification batch.
What to Ask a Partner Before Committing
Take six questions into the conversation. Which noncanonical amino acid and orthogonal pair? Which codon strategy, amber suppression or sense-codon reassignment? Which host or cell-free extract, and what is its documented suppression performance? Which conjugation route, and does it preserve the incorporated residue? Which of the five fidelity controls run on every lot? And what acceptance criteria define a passing lot before the first one is made?
A structured design-to-QC workflow supports this. MOL Changes can be used to align ncAA selection, synthesis route and analytical release criteria in one handoff, so the controls agreed at design stage are the controls run at scale. Ask for the lot-level control panel in writing, and compare it against your own specification before committing.
Common Misconceptions About Expanded Genetic Codes
Four errors show up often enough in program reviews that they are worth naming directly.
The first is that an expanded genetic code means a rewritten genome. In practice it usually means one reassigned codon and one orthogonal pair, added to a host that is otherwise unchanged.
The second is that higher incorporation efficiency means higher purity. The two can move in opposite directions: sense-codon reassignment can hold yield while purity falls, because the reassigned codon is now available to near-cognate tRNAs as well as to the orthogonal pair.
The third is that any noncanonical amino acid can be slotted into any production route. The backbone-modification split is a hard boundary, not a preference: residues that alter the backbone cannot be installed by ribosomal incorporation, and residues that require the ribosome cannot be made by SPPS.
The fourth concerns release testing.
⚠️ Warning: A single intact mass does not confirm the sequence. Without fragment ions spanning the modified residue, an epimer or a misincorporation at a nearby position can pass the same specification.
Where the Toolbox Is Heading
With those misconceptions cleared, the direction of travel is toward using more of the code at once. Where early work relied on a single orthogonal pair, recent systems have shown that mutually orthogonal pairs used together can operate in the same cell, which is what makes multi-site incorporation of different noncanonical amino acids a design option rather than a thought experiment.
A second shift is architectural. Interest has moved toward cell-free and extract-based systems that avoid permanent modification of the host genome, which shortens the cycle between designing a construct and testing it. Alongside that, four-nucleotide codon work extends the available codon space beyond the standard 64, widening the room available for reassignment.
The honest caveat is unchanged: suppression efficiency remains ncAA- and sequence-context-dependent, and not every noncanonical amino acid is compatible with every route. That is why the evaluation framework in Synthetic Peptides this guide, rather than any particular pair or platform, is the part worth keeping: expanded genetic codes for custom peptide design will keep changing, but the controls that prove what you built will not.
Next Steps
Bring a specific sequence and a specific fidelity requirement to the first technical conversation about expanded genetic codes for custom peptide design, not a general inquiry. The evaluation checklist below turns the four-part framework in this guide into questions a partner should be able to answer without hedging:
-
Which orthogonal pair, and what suppression efficiency has been observed for it in your expression host?
-
Which codon strategy: amber suppression, sense-codon reassignment, or a quadruplet codon?
-
Which route for this sequence: SPSS, cell-free synthesis, or fermentation, and why that one?
-
Which conjugation chemistry, and does it stay orthogonal to the residues already in the chain?
-
Which of the five sequence fidelity analytical controls are run per lot, and what are the acceptance criteria?
A partner who can answer all five, and say plainly where a given ncAA or route will not work, is worth more than a lower quote. MOL Changes supports this kind of design-to-QC conversation across 300+ အလုပ်လုပ်တဲ့အုပ်စုများ, SPPS and microbial fermentation, mg-to-kg scale, and HPLC/MS and sterility QC under Class 100 cleanroom conditions.
Disclosure: MOL Changes is the sponsor of this guide. The framework and evaluation criteria above are presented for research and comparison purposes. အကြောင်း
အမေးများသောမေးခွန်းများ
What is an expanded genetic code?
An expanded genetic code is a translation system in which one or more codons have been reassigned to specify a noncanonical amino acid instead of the standard one. The reassignment is targeted rather than global: an orthogonal tRNA and its aminoacyl-tRNA synthetase pair are introduced so the synthetase charges only its cognate engineered tRNA, leaving the host’s own translation machinery untouched. In the standard 64-codon frame, that leaves room to install a new chemical function at a chosen position without rewriting the rest of the proteome.
How many noncanonical amino acids can be genetically encoded?
တစ် 2025 review estimate puts the number of genetically encodable noncanonical amino acids at over 300, though that figure describes the field’s cumulative toolbox rather than what any single system can deliver. The practical count is far smaller, because each ncAA needs a compatible orthogonal pair and a host that tolerates the reassignment. Treat the headline number as an upper bound on what has been demonstrated somewhere, not as a menu you can order from.
What is the difference between amber suppression and sense-codon reassignment?
Amber suppression reads through the UAG stop codon and competes directly with release factor 1, so its characteristic failure mode is truncated product. Sense-codon reassignment swaps a codon that normally encodes a standard residue, so its failure mode is a mixed population: yield can stay high while purity falls, because the wild-type residue is still incorporated alongside the ncAA. That difference determines which controls you need, since truncation shows up in intact mass while mistranslation does not.
Which noncanonical amino acids can be made by SPPS rather than by genetic code expansion?
β-amino acids, α,α-disubstituted residues, depsipeptide linkages and many N-methylated residues are usually accessible only by solid-phase synthesis or in vitro chemistry, because the ribosome will not accept them as substrates. The genetically encodable class is narrower: side-chain modifications built on an α-amino-acid backbone. Selenocysteine is the natural exception, encoded through its own dedicated machinery rather than through an engineered pair. Peptide ထုတ်လုပ်မှု
How do you confirm that a noncanonical amino acid was incorporated at the intended site?
Confirmation requires exact mass plus sequence-localizing fragment ions that span the modified residue, typically by LC-MS/MS, together with a quantitation of incorporation efficiency and an epimer control against a synthetic reference. Intact mass alone is insufficient because it cannot distinguish the intended site from a positional isomer or a deletion variant of similar mass. The fragment ions are what localize the residue; the mass only tells you something changed.
Can noncanonical amino acids be incorporated at more than one site?
Yes, but multi-site incorporation multiplies the analytical burden rather than simply repeating a single-site workflow. Each additional position adds its own suppression or reassignment event, and the fraction of product carrying the ncAA at every intended site falls as positions accumulate, so the population becomes a distribution of partially modified species. You need to decide up front whether the assay resolves that distribution, because a method validated for one site will not automatically report on four.
Is genetic code expansion scalable for clinical-stage peptide production?
Scalability depends on which route you choose, and the two routes fail differently. Cell-free protein synthesis has demonstrated yields in the ranges reported earlier in this article, but those figures come from defined experimental systems and do not transfer automatically to a GMP process. Solid-phase synthesis scales more predictably for shorter sequences but cannot reach the residues that are SPPS-only. For clinical-stage work, the practical question is not whether the chemistry scales but whether your analytical package can prove lot-to-lot sequence fidelity at that scale.
နိဂုံး
The codon strategy you choose determines the failure mode you inherit, so the control package that proves sequence fidelity has to be specified before the first lot, not after it. That is the thread running through this guide: expanded genetic codes for custom peptide design are an evaluation problem before they are a synthesis problem.
The four decisions a partner must be able to defend in writing are the noncanonical amino acid and its suppression behavior in your sequence context, the library design and how it constrains the route, the conjugation chemistry and what it leaves intact, and the analytical acceptance criteria with their methods and limits. Each one narrows the next.
The direction of travel is toward mutually orthogonal pairs used together, cell-free and extract-based systems that leave the host genome untouched, and four-nucleotide codons that extend the available codon space past the standard 64. The honest caveat is that suppression efficiency stays dependent on the ncAA and the surrounding sequence, and not every ncAA is compatible with every route.
Use the checklist in Next Steps as the basis for your first technical conversation.
About the author: [Author name], [credentials], writes on peptide design and analytical control strategy for MOL Changes.
Disclosure: MOL Changes provides peptide design, synthesis and analytical services, including the capabilities discussed in this guide.