What does advanced precursor ion selection actually change compared with conventional TopN DDA?
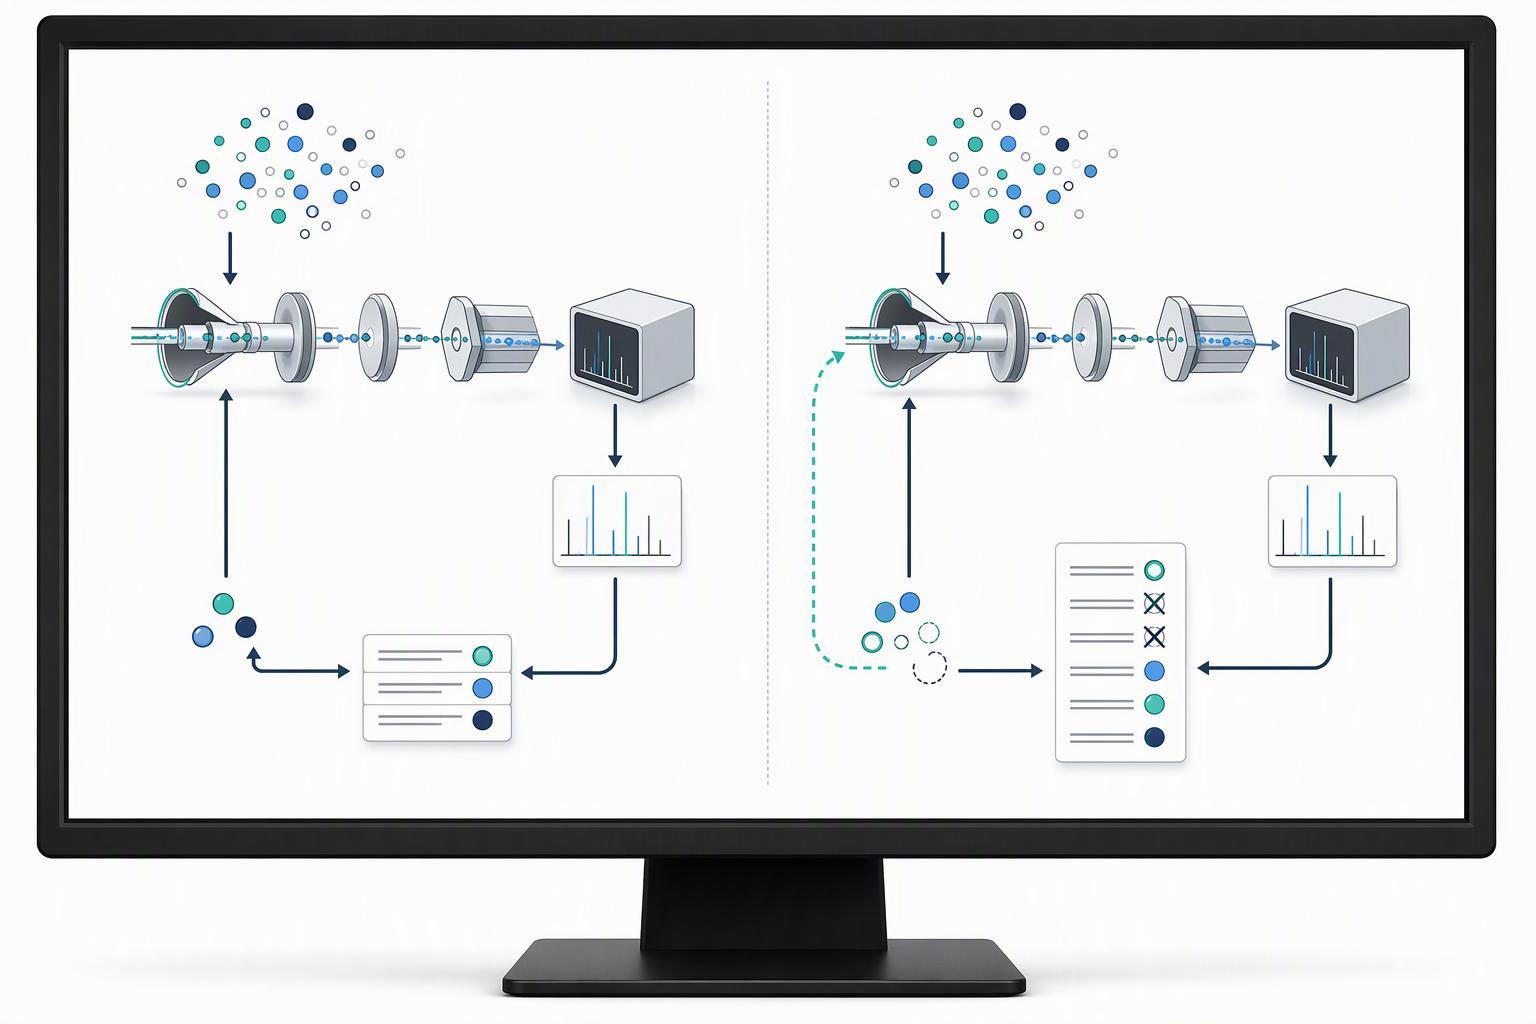
Synthetic Peptide Peptides Growth Hormones It changes the sampling loop, not the detector. Conventional TopN DDA selects the N most intense eligible precursors in each MS1 cycle, and dynamic exclusion prevents immediate reselection, so selection stays largely intensity-driven and abundant peptides are sampled again and again (Kreimer et al., J Proteome Res, 2016). The instrument is working correctly; the strategy simply keeps returning to the same neighborhood.
Kreimer et al. compared two iterative-exclusion strategies: excluding all previously fragmented precursors and excluding only identified peptides. Cov no yog tsim qauv sib txawv nrog cov txiaj ntsig sib txawv. Piav qhia tias daim ntawv teev kev txwv twg tau siv ua ntej hais txog qhov nce, thiab khaws cia HeLa digest thiab LTQ Orbitrap XL scope ntawm kev tshawb fawb. Kev tshawb fawb thawj.
Ib hom thib peb txhawb kev txwv ntxiv: kev tshawb nrhiav database lub sijhawm tiag tiag thaum tau txais tso cai rau kev tshem tawm raws li peptide identity es tsis yog los ntawm m/z thiab sijhawm xwm txheej. Kev ua haujlwm simulation thaum ntxov ntawm adaptive peak selection pom tias qhov no tsuas ntxiv txog ib qho xwb 1% txiaj ntsig tshaj kev xaiv daim ntawv teev kev cais tawm ib txwm (arXiv preprint 1207.5848, n.d.). Saib tus naj npawb ntawd ua ib qho txiaj ntsig simulation, not a benchmark, thiab tsis txhob hais tias nws yog ib qho cuab yeej ntsuas.
Hauv qhov kev tshawb fawb tau hais 2016 kev tshawb fawb, cov TopN saturation ib txwm muaj 12,500 cov peptides tshwj xeeb yog ib qho extrapolation. Cov kev sim sib xyaw ua ke-kev tshem tawm tau dhau qhov ntawd 16,000 kev txheeb xyuas. Kev piv txwv qhia txog kev xaiv qauv ntxiv hauv qhov qauv ntawd, not a universal 29% gain over a matched single-run control.
Searching co-isolated species can increase identification depth in the cited 2025 kev tshawb fawb. Its reported percentages use different comparisons and must retain their own denominators; they should not be combined into an average that exceeds a stated range or merged with iterative-exclusion gains.
Precursor selection affects which fragmentation evidence is acquired. An unfragmented feature may still be present in MS1 data; it cannot be assigned equivalent sequence confidence without adequate supporting evidence. Improved searching can recover information already present in acquired spectra.
Why can technical-replicate overlap be low without the method being irreproducible?
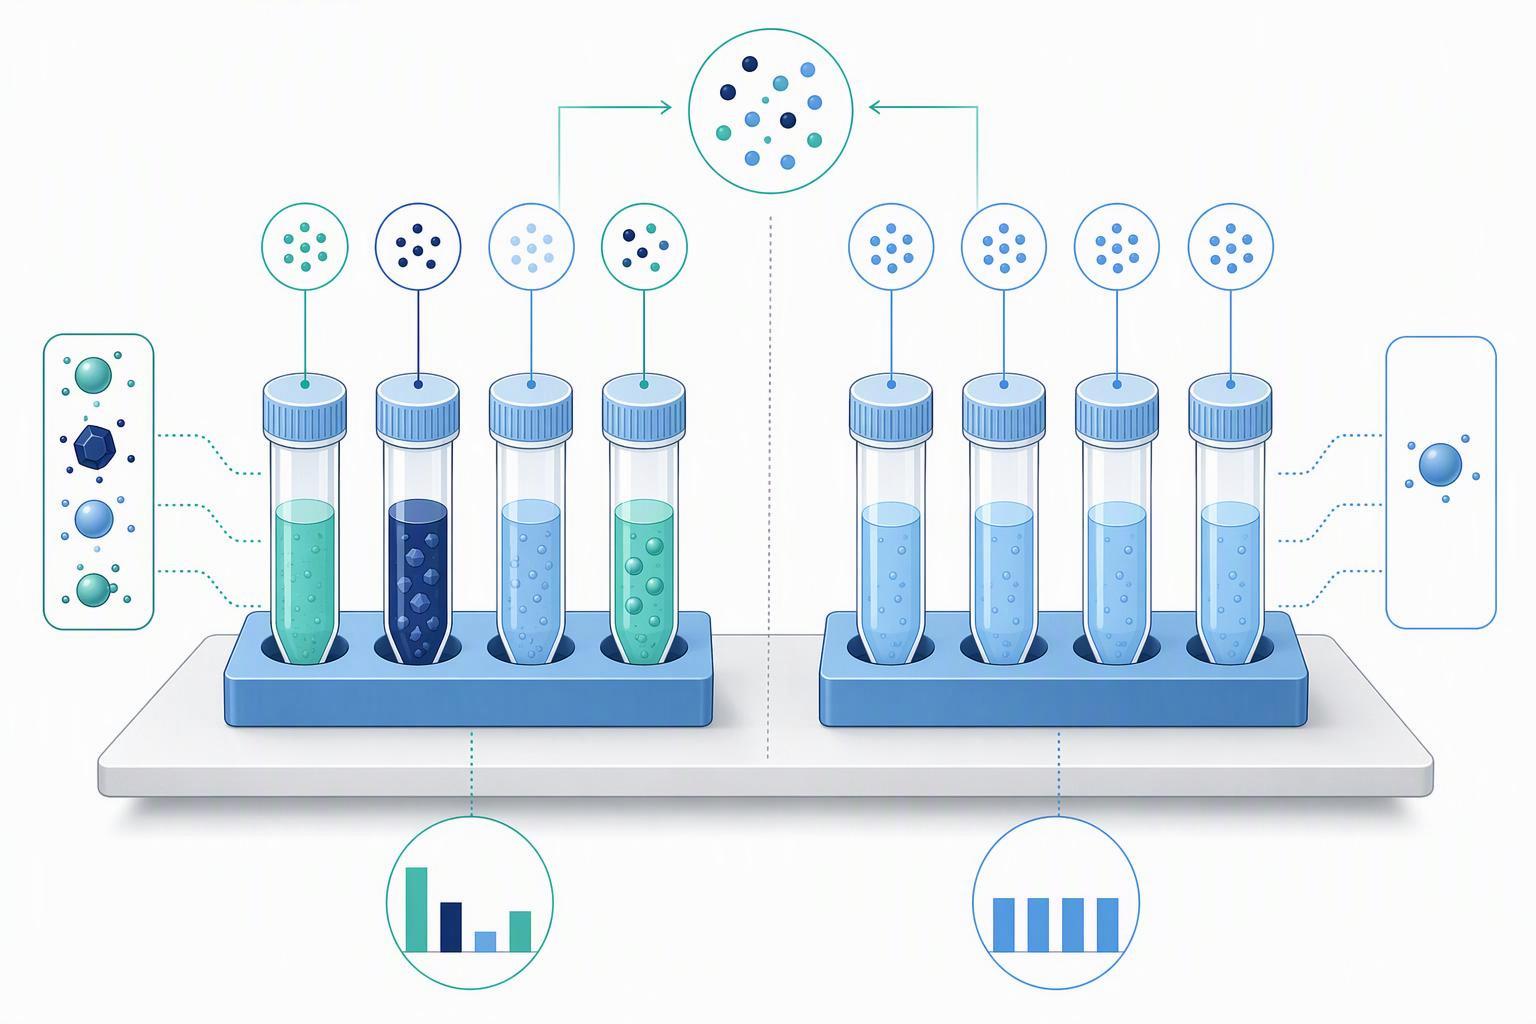
Because low overlap and poor reproducibility are different measurements, and a discovery-depth design can produce the first while the method remains perfectly repeatable. The long-standing range for replicate peptide overlap in conventional DDA is 35–60% between pairs of technical replicates, a figure that comes from a 2010 re-analysis on LTQ and older Orbitrap instruments (Tabb et al., J Proteome Res, 2010). That study also found the overlap was independent of sample complexity: a 48-protein mixture gave a median 44% overlap, a protein standard mixture 46%, and a yeast digest 45% (Tabb et al., J Proteome Res, 2010). Repeatability correlated with precursor intensity, so low-abundance peptides were the ones that dropped out.
Q. h, o, v. If your design is meant to demonstrate reproducibility, n, t: a, w, d, technical controls, y (o).
g. A direct DDA-versus-DIA comparison in the same samples found more than 92% of peptides consistently identified across replicates in DIA data versus less than 77% in DDA data, with protein-level consistency of 99.0/98.2/98.2% for DIA against 95.6/95.4/96.2% for DDA (PMC12801617, 2025). An eight-replicate completeness comparison in tear fluid found DIA at 78.5% peptide completeness versus 48% for DDA, with median CVs of 10.6% thiab 22.3% respectively (J Mass Spectrom Adv Clin Lab, 2025). Two different metrics, presence/absence consistency and coefficient of variation, point the same way.
The honest gap: no source in this set re-measures the 2010 overlap figure on current instrumentation. The 35–60% range should be dated whenever it is quoted, and the DIA-versus-DDA evidence covers cell lines and tear fluid only. No source here compares the two modes on a phosphoproteome or other PTM-enriched sample, so any claim about DIA versus DDA for modified peptides would be unsupported.
Before acquisition, distinguish a discovery-depth design from a repeatability study. Low overlap after deliberate exclusion can indicate complementary sampling, but also check identification confidence, total coverage and sample quality; low overlap alone does not prove the strategy is working.
How much sequence coverage is enough, and where does coverage have to fall?
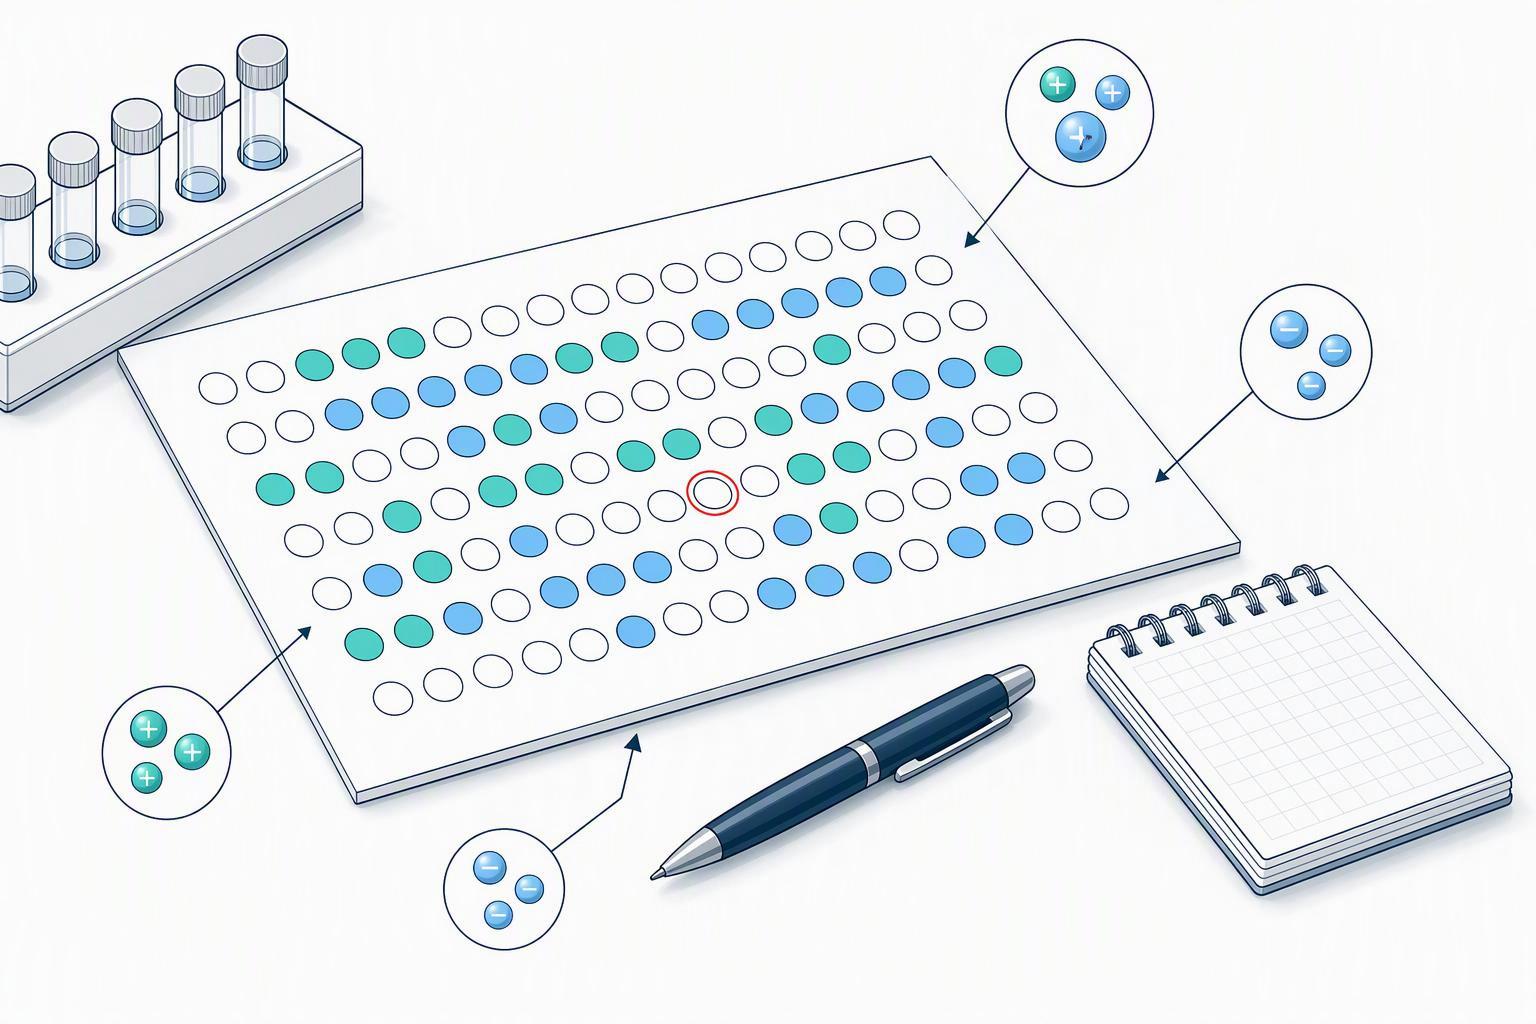
Define the coverage metric before setting a criterion. Protein sequence coverage counts residues represented by identified peptides; fragment-ion coverage of a synthetic peptide is a different measure. Neither percentage alone establishes residue order, kev hloov chaw lossis stereochemistry. Teem cov ions kuaj mob thiab kev kuaj orthogonal uas tsim nyog.
Txoj cai tso raws li qhov kev piav qhia ntawd. Rau peptide hloov kho lossis cim npe, kev npog yuav tsum muaj cov seem uas nqa kev hloov lossis cim npe. A 95% daim ntawv qhia kev npog uas tso qhov chaw hloov kho tsis tau npog 5% tsis txhawb nqa ib qho kev lees paub tshwj xeeb ntawm qhov chaw, txawm tias feem pua zoo li cas.
Qhov ntawd yog kev coj ua ntawm cov neeg muag khoom, tsis yog ib qho kev cai tswj hwm, thiab nws yuav tsum tau cim npe li ntawd hauv txhua qhov kev piav qhia uas koj sau.
Qhov uas tus neeg tshuaj xyuas tuaj yeem muab koj rau yog cov ntawv qhia. Cov lus qhia hauv phau ntawv xov xwm uas tus nyeem ntawv tuaj yeem raug cai yuav tsum muaj kev tso cai rau precursor-ion thiab fragment-ion, lub tshuab tshawb nrhiav thiab version, lub database, txoj kev kwv yees FDR, and the software or method used to evaluate modification site assignment, with annotated spectra for every peptide where a modification site is reported (MCP Tutorial for Proteomics Data Submission, MCP author guidance). The minimum-information checklist adds software name, version and manufacturer, databases queried with versions and entry counts, and the parameter files (MIAPE-MSI 1.1, 2008-02-05). MIAPE is the 2008 checklist and remains at version 1.1; it is not a new requirement.
So the practical answer to “what coverage number will a reviewer accept” is: state the threshold you applied, state where coverage falls relative to Semaglutide Peptide the modified residue, and report the parameters that let someone reproduce the calculation. A number without those three things is not defensible.
How do you localize a modification or a label rather than just confirm intact mass?
b, with its own score, d. a: i, m, 10%, 29% thiab 53% respectively have mass-identical isomers, n 14% thiab 38% (t, J Proteome Res, 2004). a, w.
v. A current implementation compares the best-scoring peptidoform with the modification at a site against the best-scoring peptidoform without it, ignores shared peaks because they provide no discrimination, and drives localization confidence only from discriminating peaks (PTMProphet, 2019). That implementation applied localization at iProphet probability thresholds of 0.9 for two datasets and 0.8 for a third, the latter corresponding to 0.4% estimated PSM error and 97.9% PSM sensitivity, and reported results at 5% false localization rate and below 1% FLR (PTMProphet, 2019).
The classic localization thresholds are score-based and should not be treated as universal acceptance criteria. AScore 19 corresponds to p approximately 0.01, los yog 99% certainty, and later phosphoproteomics practice from the same laboratory used a more liberal p < 0.05, AScore > 13; Spectrum Mill requires a score difference greater than 1.1 between the top two localizations for confident localization (Modification Site Localization Scoring, 2012). The same review warns that probability-based scores rest on an unrealistic assumption that all masses are equally likely to be observed at random, and recommends treating them as scores subject to a user-set threshold rather than as accurate measures of certainty.
That warning is confirmed by how thresholds are actually chosen. PTMProphet describes selection of the localization probability threshold as largely an arbitrary choice made by the user, to be set by the error rate the user accepts (PTMProphet, 2019). No standard fixes a number, so the defensible move is to state the threshold, state the error rate it corresponds to, and report the localization rate alongside the identification rate.
For a labeled peptide, an expected intact-mass shift supports a proposed composition but does not prove the label chemistry or attachment site. Use site-determining fragments and, where necessary, an orthogonal structural method to test the proposed label and linkage.
Which orthogonal technique answers which identity question?
Each technique answers a different question, and the mapping matters more than the count. s 2025 European guideline for synthetic peptides, in force since June 2026, recommends use of at least two orthogonal methods for identification as part of specification and release, and lists mass, e, LC-MS, peptide mapping, bioactivity, amino acid analysis or NMR as appropriate, with the combination required to unambiguously confirm the sequence (EMA, Guideline on Development and Manufacture of Synthetic Peptides, 2025-12-04, effective 2026-06-01).
The regulatory logic underneath is performance-based rather than numerical. ICH Q2(R2) requires identification to demonstrate the capability to distinguish the analyte by unique molecular-structure aspects, confirmed by positive results against a reference material plus negative results from samples lacking the analyte, and where a procedure is not sufficiently discriminating, an additional procedure should be used (ICH Q2(R2), adopted 2023-11-01, corrected 2023-11-30). The specificity requirement is a capability test, not a count of tests.
Reference-standard practice for peptide identity converges on the same direction without fixing a number: multiple orthogonal techniques are typically used to verify chemical structure and chemical identity, including HPLC retention time, NMR, MS and chiral testing, and multi-laboratory studies use NMR, peptide mapping, HPLC and amino acid analysis (Pharmaceutical Research, 2023). HPLC identity in that practice relies on retention-time comparison against a reference standard, which is why a retention time without a standard is not an identity result.
The method-to-question mapping that Peptides Wholesale Supplier follows from these sources:
|
Identity question |
Technique that answers it |
What it does not answer |
|---|---|---|
|
Is the intact mass correct? |
LC-MS or MALDI-TOF intact mass |
Sequence, positional or stereochemical features |
|
Is the sequence correct? |
MS/MS with sequence coverage, or peptide mapping |
Labile modifications, partial coverage gaps |
|
Where is the modification or label? |
MS/MS site-determining fragments with a stated localization threshold |
Whether the site is functionally relevant Melittin |
|
Is the stereochemistry correct? |
Validated chiral analysis; ordinary amino acid composition analysis alone does not establish stereochemistry |
Position of a modification |
|
Is it the same material as the standard? Custom Peptide Wholesale |
HPLC retention time against a reference standard |
Anything the standard itself does not establish |
The COA review habit of keeping each conclusion with its method is the practical version of this table: chromatographic purity describes chromatographic homogeneity and does not independently establish chemical identity, intact mass alone may not establish every sequence, positional or stereochemical feature, and identity and purity should be reported separately and attached to the methods that support them (Vector E Lab, 2026-09-28).
What has to be written down before acquisition for the identity claim to be defensible?
The record has to be complete enough that someone else can rerun the same or a similar search on the same or another engine. Hom kev hloov pauv uas nqa txoj kev tshawb nrhiav yuav tsum tau SpectrumIdentificationProtocol tshaj tawm hom tshawb nrhiav xws li peptide-level scoring lossis modification localization scoring, yuav tsum muaj search engines sawv cev hauv software list, thiab tsim rau qhov rov ua tau zoo ntawd (mzIdentML 1.3.0, June 2024).
Cov ntaub ntawv pre-acquisition, sib sau los ntawm cov qauv tshaj tawm saum toj no:
-
Selection strategy thiab nws cov parameter. TopN value, isolation window, dynamic exclusion duration, thiab seb daim ntawv exclusion puas txuas ntxiv ntawm kev khiav.
-
Tolerances. Precursor thiab fragment mass tolerance, hais ua lej. s 2016 study used 10 ppm thiab 0.5 Da (Kreimer et al., J Proteome Res, 2016); instrument-level accuracy uas txoj kev yuav tsum tau phim yog qis dua 3 ppm RMS dhau lawm 24 h nrog external calibration thiab qis dua 1 ppm RMS nrog internal calibration ntawm Orbitrap platform tam sim no (Thermo Fisher specification sheet, vendor sheet currently published).
-
Search engine and version, database and version with entry count, and the FDR estimation method. Target-decoy searching is the accepted way to distinguish correct from incorrect identifications, and because most search engines return results even for unmatchable spectra, error rates must be estimated from the score distribution (Elias & Gygi, Nature Methods, 2007). Per-peptide confidence comes from a probabilistic model that computes the probability each assignment is correct, enabling filtering with predictable error rates (Keller et al., Anal Chem, 2002).
-
The site-assignment method and its threshold, with annotated spectra for every peptide where a modification site is reported.
-
Replicate structure. Number of replicates, and whether they are biological, process or technical.
-
The archive identifier. PXD identifiers are persistent, unique and mandatory as the main identifier for originally submitted datasets, with metadata plus raw and processed files deposited together, and RPXD identifiers for reanalysed datasets (ProteomeXchange consortium, Nucleic Acids Research, 2026-01-06).
Txoj cai txiav txim, applied before acquisition: if you cannot write down the selection strategy, the tolerances, the search parameters, the localization threshold and the replicate structure in advance, the identity claim will not be defensible afterward. Every one of those fields is a decision, and each one is cheaper to make before the run than to reconstruct after it.
Cov Lus Nug Nquag Nug
Does low technical-replicate overlap mean my method is bad?
Not necessarily. Conventional DDA selects only the most intense precursors in each cycle, so low overlap between replicates is expected sampling behavior rather than a reproducibility failure (Tabb et al., J Proteome Res, 2010). The question to ask is what the replicate design was meant to demonstrate.
Can I quote the 29% figure as a general benchmark?
PM. It comes from one 2016 study on an LTQ Orbitrap XL with a HeLa digest and a 120 min gradient (Kreimer et al., J Proteome Res, 2016). Quote it with that scope attached, or state the mechanism qualitatively.
What sequence coverage should I put in a specification?
No regulator-backed minimum exists. State the threshold you applied, confirm that coverage includes the residue carrying the modification or label, and report the search parameters that let a reviewer reproduce the calculation.
Is intact mass enough to confirm identity?
PM. Among peptides differing by one, m, 10%, 29% thiab 53% have mass-identical isomers (t, J Proteome Res, 2004). Mass is one orthogonal method, not a complete identity claim.
Do I need exactly two orthogonal methods?
s 2025 European guideline recommends at least two for synthetic peptide identification (EMA, effective 2026-06-01), while ICH Q2(R2) frames the requirement as specificity-based rather than a fixed count (ICH, 2023). The combination has to unambiguously confirm the sequence; the number follows from that.
Xaus lus
The identity claim is built before acquisition, not after it. Precursor-selection strategy decides which peptides get sampled, replicate design decides whether overlap is informative or accidental, coverage reporting decides whether the modified residue is actually inside the evidence, and orthogonal characterization decides whether the claim survives a reviewer who knows that mass alone leaves isomers unresolved.
The next step is a pre-acquisition record: selection strategy, tolerances, search parameters, localization threshold, replicate structure and archive identifier, written down and version-controlled before the first injection. If any field is missing, fix it before the run rather than in the response to a reviewer.
For teams comparing service scopes for custom, modified and labeled peptides, request a quotation that states the analytical parameters above rather than a purity figure alone.
The analytical standards and method comparisons cited are independent published sources.*