What the Translation Gap Is and What Bench-Ready Means
Dobavljač prilagođenih peptida Peptide Calc The translation gap is the distance between a computationally ranked candidate and a peptide that can be reproducibly made, characterized and tested. Bench-ready is the checkable state on the other side of that distance: a defined sequence and format, demonstrated synthesis feasibility, an analytical data package that supports each claim, stated handling conditions, and an assay the material is actually fit for.
The clinical layer shows why the gap matters commercially. The 2011–2020 industry baseline was a 7.9% likelihood of approval from Phase I across 12,728 phase transitions (BIO / Informa Pharma Intelligence / QLS Advisors, 2021). The first analysis of AI-native pipelines found 80–90% Phase I success but only about 40% in Phase II, a figure the authors describe as resting on a limited sample size (Jayatunga et al., Drug Discovery Today, 2024). A 2025 commentary built directly on those numbers states that safety and tolerability trend better than traditionally developed molecules, 90% versus under 65%, while Phase II proof-of-concept success sits at 40%, in line with historic industry averages, and adds that there are not yet enough cases to power statistical analyses (Jacobson, npj Drug Discovery, 2025).
Two limits on the evidence belong in the same paragraph as the numbers. No peer-reviewed source quantifies the share of AI-designed peptides that fail synthesis, and no source defines “AI-discovered” operationally, whether that means AI used for target identification, molecule design, ili oboje. Closing the translation gap in AI peptide design therefore cannot be measured against a published failure rate. It has to be managed as a sequence of engineering decisions, which is what the remaining sections set out.
How Peptide AI Models Are Trained and What Data They Need
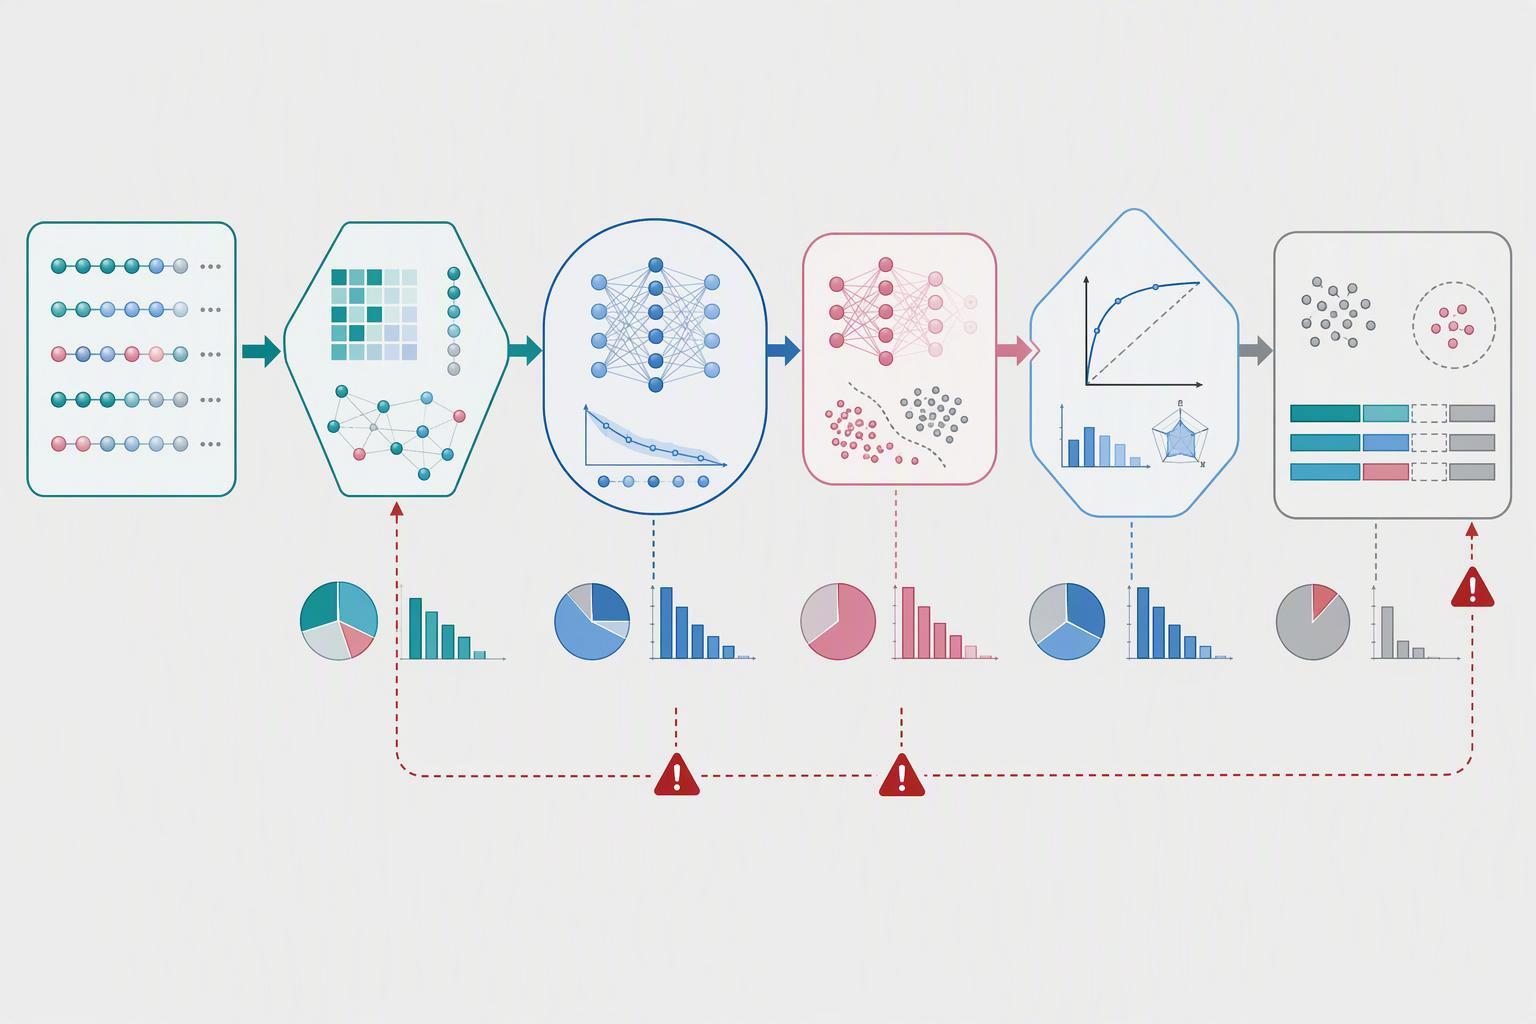
Peptide models learn from a sequence representation, a pre-training corpus, a fine-tuning set with labeled positives and negatives, and an evaluation split, and the quality of the last two determines whether reported performance means anything. AMPGen’s training set is a useful concrete case: 10,249 unique antimicrobial peptide sequences compiled from six public databases, od kojih 9,854 carry antibacterial targets, reduced to 9,964 positives after filtering to 5–65 amino acids, paired with 11,989 non-AMP sequences drawn from UniProt as negatives (AMPGen, Communications Biology, 2025). The generator itself was pre-trained on OpenFold data covering 401,381 multiple sequence alignments for roughly 132,000 unique PDB sequences.
That negative set is the part most projects underinvest in. Filtering UniProt for sequences of 5–65 residues while excluding 17 keywords such as antimicrobial, antibiotic, antibacterial and toxin produces negatives that are non-AMP by annotation, not negatives that were measured and found inactive. No stable public figure exists for the share of inactive records in peptide activity databases, which is why the composition of a specific set, not a general claim about database balance, is the honest way to describe this.
Evaluation is the second weak point. An audit of 51 benchmark configurations spanning Polaris, TDC, MoleculeNet and DTI found cross-split contamination in the vast majority of datasets, with mean nearest-neighbour ECFP Tanimoto similarity between test and training compounds of 0.494, 0.559, 0.589 i 0.779 odnosno (benchmark audit, PMC, 2026). Under injected label conflicts, the mean ROC AUC fell by 0.317. A peptide model evaluated on a split that shares near-duplicate sequences with training is reporting a number that will not survive synthesis.
Why Computationally Promising Peptides Fail at Synthesis and in the Assay
Peptides fail at the bench for chemistry reasons that a sequence-level activity model does not see. Teške sekvence, defined as those forming strong inter- or intramolecular non-covalent interactions that produce insoluble aggregates and block complete deprotection and coupling, remain a challenge above 50–60 amino acids even with automated synthesis, and sequences longer than 50 residues often need fragment condensation or native chemical ligation (Frontiers in Chemistry, 2020).
The cited two-peptide study changed process conditions as scale increased. Its yields describe those routes and experiments, not a planning range for every sequence. Compare a proposed scale-up through matched process and analytical data.
The cited AMPGen paper reports synthesis and antibacterial testing of selected candidates as well as computational screening. Keep measured outcomes distinct from predictions and retain the relevant organism, assay and candidate-selection denominator; the results do not establish clinical efficacy or a success rate for all generated sequences.
How to Filter AI Candidates Against Real Synthesis Constraints
Filter candidates against synthesis constraints before ranking them for activity, not after a failed campaign. The practical sequence runs: allowable residues and protecting-group compatibility, then hydrophobic-run and aggregation-risk scoring, then multi-disulfide and cyclization feasibility, then terminal and side-chain modification compatibility, then the length ceiling. Each gate is a yes-or-no on a specific sequence, and a candidate that fails any gate should be re-designed rather than carried forward with a note.
Structure prediction supports the middle gates rather than replacing them. AlphaFold 3 predicts the joint structure of complexes including proteins, nucleic acids, small molecules, ions and modified residues from polymer sequences, residue modifications and ligand SMILES, and reports substantially higher accuracy for protein–ligand interactions than docking tools such as Vina (P = 2.27 × 10⁻¹³) and for antibody–antigen complexes than AlphaFold-Multimer v2.3 (P = 6.5 × 10⁻⁵) (Abramson et al., Priroda, 2024). Those are significance values, not a headline percentage improvement, and they say nothing about whether the peptide can be assembled on resin.
Sequence length is a risk factor, not a universal synthesis ceiling. Hydrophobic runs, modifications and topology should trigger feasibility assessment; four consecutive hydrophobic residues do not automatically require redesign or fragment ligation. Choose a route using construct-specific experiments.
|
Vrata |
What it screens |
Failure response |
|---|---|---|
|
Residue and protecting-group Amplified Peptides compatibility |
Whether required residues and chemistry coexist |
Substitute residue or change strategy |
|
Hydrophobic-run and aggregation risk |
Consecutive hydrophobic stretches, β-sheet propensity |
Redesign or plan fragment condensation |
|
Disulfide and cyclization feasibility |
Multi-disulfide regiochemistry, Peptide Information Manufacturer head-to-tail or lactam closure |
Adjust cyclization chemistry or drop Growth Hormone Peptides |
|
Modification compatibility |
Terminal, side-chain, označiti, linker and lipid additions |
Re-sequence the modification site |
|
Length ceiling |
Practical limit for complex modified sequences |
Split into fragments or ligate |
What Analytical Data Package Makes a Peptide Defensible at the Bench
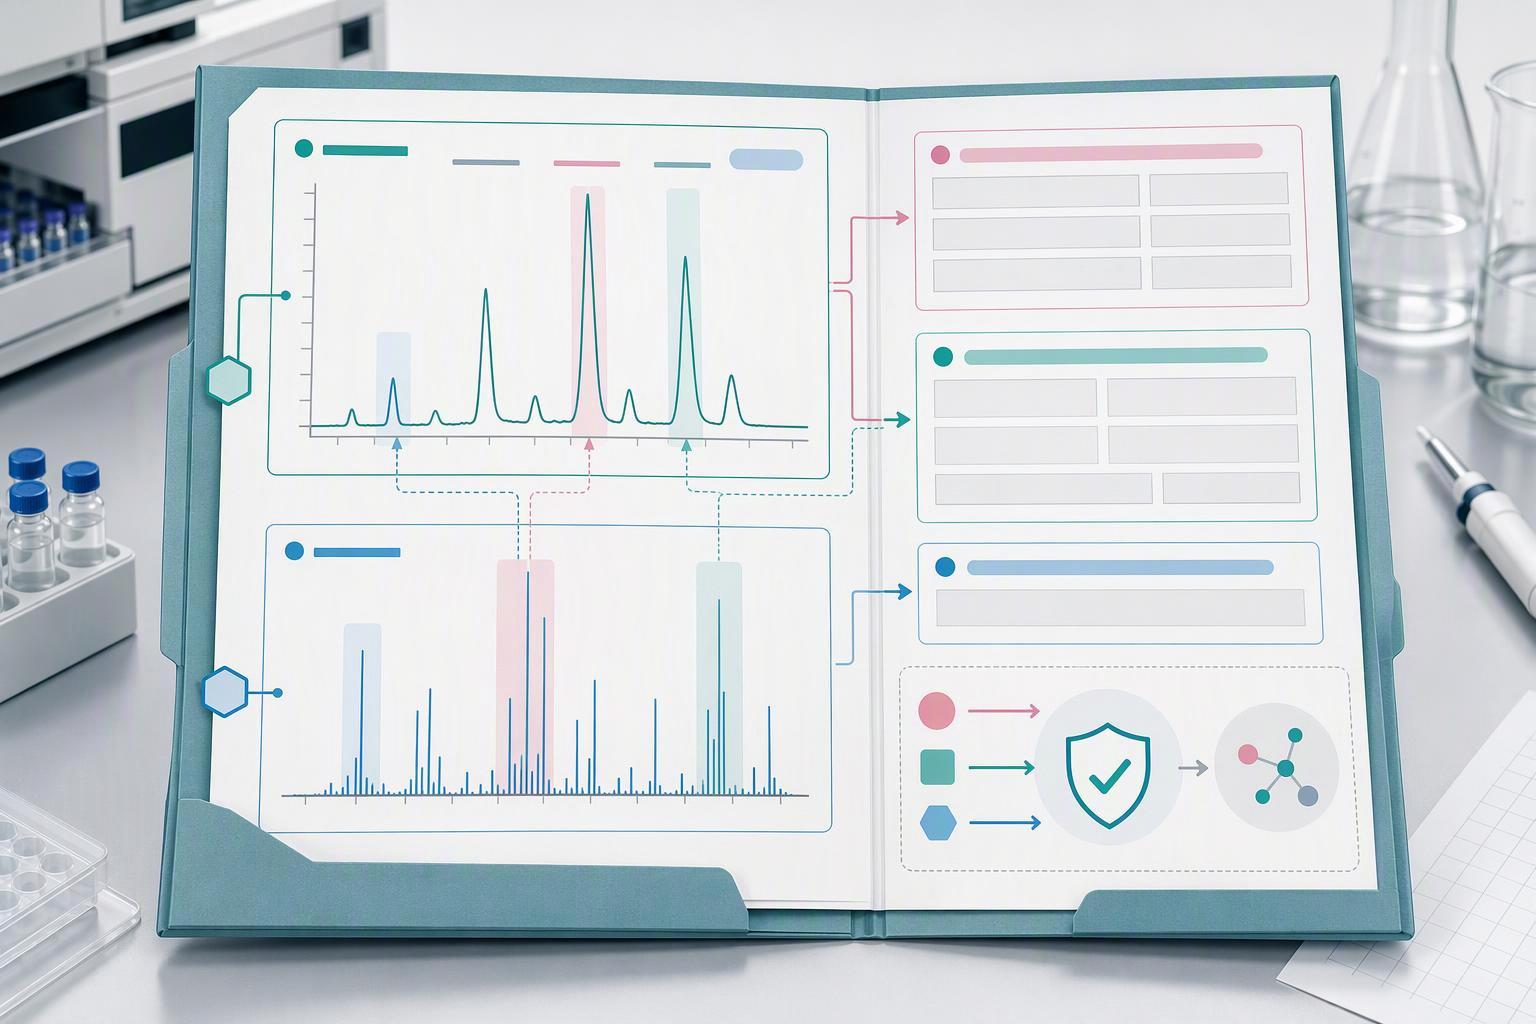
A defensible package separates purity, identitet, sadržaj, stability and assay suitability into distinct claims, each with its own method and its own evidence. Smjernice EMA-e o razvoju i proizvodnji sintetičkih peptida, usvojeni 4 prosinac 2025 and effective 1 lipanj 2026, treats purity as one of the most important critical quality attributes for synthetic peptides, requires acceptance criteria for individual fractions and the main pool to be stated and justified, and calls for orthogonal purity characterization across size-based, charge-based and hydrophobicity-based separation (EMA, 2025).
Identity is not purity, and the guidelines say so in different places. ICH Q6B holds that absolute and relative purity are difficult to determine and highly method-dependent, so purity is assessed by a combination of analytical procedures, while identity tests should be highly specific to the molecule and may require more than one physicochemical, biological or immunochemical test (I Q6B, 1999). The EMA guideline recommends at least two orthogonal identification methods at specification and release, drawn from mass, relativno vrijeme zadržavanja, LC-MS, mapiranje peptida, bioaktivnost, analiza aminokiselina ili NMR, and splits impurities into peptide-related and non-peptide categories (EMA, 2025).
Use the final ICH Q2(R2) framework for applicable analytical validation and justify the study design for the intended decision. Uvjeti skladištenja, batch count and duration must be selected for the product and development stage rather than inherited as a universal screening-material requirement.
How to Scale from mg Screening to kg Production Without Losing Lot-to-Lot Consistency
Scale-up changes the process, so the purity and yield you validated at screening scale are not the numbers you should promise at production scale. The Guzmán data show the size of that shift: the same peptide moved from 8.0% yield and 23.9% crude purity at 10–20 mg to 53.5% yield and 64.4% crude purity at 3–4 g, and the second peptide from 36% i 62.1% do 78.5% i 98.7% (Guzmán et al., Electronic Journal of Biotechnology, 2023). Because protocol and conditions changed with scale in that study, the honest reading is that scale-up requires re-optimization, not that a fixed penalty applies.
Lot-to-lot consistency is controlled through the specification, not through the yield figure. The EMA guideline expects process parameters for isolation operations to be described, requires measures to prevent cross-contamination when different peptides are purified on the same column, and requires a fate-and-purge assessment of starting-material impurities that may carry through to the final peptide (EMA, 2025). Brisanje i skraćeni nizovi, formed by incomplete coupling or deprotection and capped by acetylation, are the impurity class that most directly reflects process control, and the guideline expects their formation to be prevented by repeated coupling and systematic capping rather than corrected downstream.
Stability studies should support the actual storage, handling period, intended use and development stage. ICH registration recommendations for primary batches and submission duration are not a universal twelve-month waiting period for research peptides. Define a phase-appropriate protocol and acceptance criteria.
How the Closed Loop Works When Assay Results and Failures Go Back Into the Model
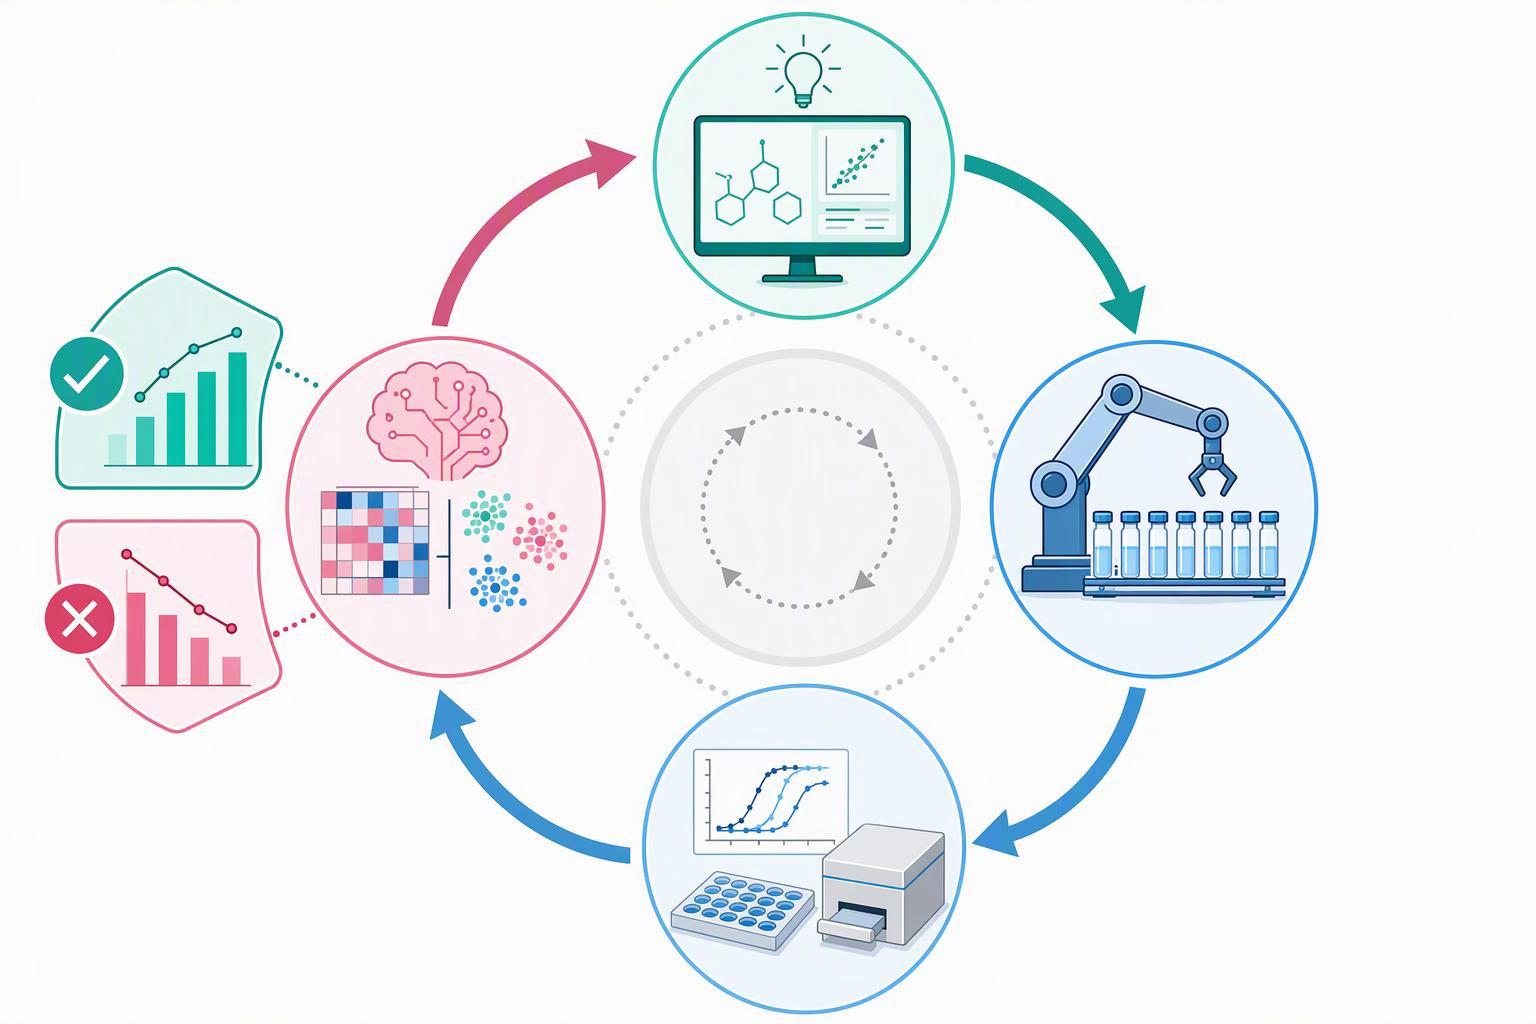
The closed loop only works if failures and negatives are recorded as distinct labels rather than collapsed into one inactive bucket. The documented cycle is design and prefilter against hard constraints including synthesis feasibility, agregacija, toksičnost, solubility and material compatibility; make and assay; curate outcomes by attaching each result to the exact sequence, construct, batch, assay protocol, koncentracija, replicate, kontrole, QC status and model version; update models; then re-rank and select the next batch balancing predicted utility, uncertainty, diversity, novelty and practical feasibility (multimodal foundation model review, PMC, 2026). Tvornica peptida po narudžbi
The four label categories are what make the difference. Quantitative measurements carry a value and a method. Confirmed negatives carry evidence that the peptide was made and tested and did not work. Censored results carry a measurement that fell outside the assay’s range. Technical failures carry a synthesis or assay that did not produce interpretable data. Merging those into “inactive” teaches the model that a failed coupling and a genuine negative are the same thing, which is the opposite of what the next design round needs.
Throughput is the practical constraint on how fast the loop turns. A parallelized 192-reaction campaign completed in four days, a four-fold increase over a typical sequential approach, with active learning in batches of eight, is the concrete benchmark for campaign-scale iteration (self-driving lab account, PMC, 2022). That account also states the system is not fully autonomous and that some steps still require human intervention such as loading new vials or chemicals, which is the same human-in-the-loop caveat the 2025 commentary makes when it says AI is a tool to enhance, not replace, scientific intuition (Jacobson, npj Drug Discovery, 2025).
Where Regulation and Evidence Stand, and What Remains Unproven
Regulation for AI in drug development is principles-based and still forming, while peptide chemistry expectations are already concrete. EMA and the FDA jointly published ten principles for good AI practice in the medicines lifecycle on 14 siječnja 2026, covering evidence generation and monitoring from early research through manufacturing and safety monitoring, addressed to developers and marketing authorisation applicants and holders, and intended to underpin future jurisdiction-specific guidance (EMA, 2026). EU guideline development builds on the EMA AI reflection paper published in 2024. FDA u siječnju 2025 draft guidance on AI for regulatory decision-making is nonbinding and organized around context of use, defined as how a model is used to address a particular question, with sponsors establishing model credibility for that context (FDA, 2025).
Čitajte zajedno, the peptide guideline is the operational template and the AI principles sit on top of it. The EMA synthetic-peptide guideline already imposes starting-material justification, impurity reporting, identification and qualification thresholds, and orthogonal identification, and requires analytical procedures to be described in enough detail to be repeated by an Official Medicines Control Laboratory (EMA, 2025). No source connects the EMA–FDA AI principles to peptide-specific AI design, and no source gives a regulatory pathway or timeline for AI-designed peptides reaching approval.
The clinical record is mixed and should be read as such. DSP-1181, the first AI-designed drug to enter humans, was discontinued in 2022 before Phase II; REC-994 was discontinued in 2025 after longer-term data failed to sustain earlier efficacy trends; rentosertib reached Phase IIa for idiopathic pulmonary fibrosis in 2024, s 18 months from target discovery to preclinical candidate nomination (AI in Drug Discovery: Clinical Failures, Regulatory Reality, PMC, 2026). The 2025 commentary states plainly that AI efforts so far have not resulted in more effective drugs, while the 2024 analysis frames its findings as early signs of clinical potential. What remains unproven is efficacy, not speed.
Često postavljana pitanja
Are AI-designed peptides harder to synthesize than natural ones?
No source establishes that. Difficulty tracks the sequence itself, not its origin: aggregation-prone stretches, bulky or hindered residues, and length above roughly 50 do 60 amino acids create the same coupling and deprotection problems whether a model or an evolution wrote the chain (Frontiers in Chemistry, 2020). What changes with AI is throughput. Models propose candidates faster than a bench can triage them, so hard sequences arrive in larger batches and the failure rate looks worse than it is.
What purity does a peptide need for a cell assay versus an in-vivo study?
There is no single number. Smjernice EMA-e o sintetskim peptidima, djelotvoran 1 lipanj 2026, asks for acceptance criteria justified for the specific intended use rather than a fixed threshold (EMA, 2025). Set the limit from what the assay tolerates: counterion and truncated species that shift an in-vitro readout may be irrelevant in vivo, and the reverse also holds.
Is a certificate of analysis enough to release a lot?
Ne. A CoA reports what the supplier measured; it does not by itself confirm identity. At least two orthogonal identification methods are recommended at specification and release, so mass spectrometry and a chromatographic or sequencing method should agree before the lot is accepted (EMA, 2025).
What should happen to a failed synthesis in the training set?
Label it a technical failure, not an inactive. Quantitative results, confirmed negatives, censored values and failed runs carry different meanings, and merging them destroys the signal a closed-loop AI peptide design workflow needs (multimodal foundation model review, 2026). Attach each label to the sequence, construct, batch, protokol, koncentracija, replicate, kontrole, QC status and model version.
Has AI actually improved clinical efficacy?
The evidence is contested, and the later reading is negative. Early reports of accelerated discovery have not been matched by demonstrated gains in clinical endpoints, so treat computational speed as a process improvement rather than proof of better outcomes (multimodal foundation model review, 2026).
Zaključak
Compare like-for-like endpoints: Phase I completion is not the same as eventual approval after entering Phase I. The cited AI-program samples and historical industry cohorts differ in selection, size, dates and follow-up. They do not establish an AI advantage by comparing 80–90% with a 7.9% approval probability.
What closes the gap is a workflow, not a model. Filter candidates against synthesis constraints before ranking them, build the analytical package so purity, identitet, sadržaj, stability and assay suitability each stand on their own evidence, plan scale-up around re-optimized process parameters and three primary batches, and record failures as their own labels so the next design round learns from them. The constraint checklist in the synthesis-feasibility section is the practical starting point, and the analytical data-package checklist is the companion for the bench stage. Both are worth adopting before the next campaign, ne nakon toga.