What the MIT antibiotic campaign and the enzyme search actually demonstrated
Peptides Supplier Factory Peptide Tech The two campaigns demonstrated search and prioritization at scale, not validated drug candidates. の Cell work combined fragment-based and de novo generative models and pushed 36 million predicted compounds through filters to 24 synthesized molecules, seven of them antibacterial (Krishnan et al., Cell, 2025). The gonorrhoea track’s funnel shows the cost: 6,937,677 generated molecules, 678 left after filtering, 80 prioritized for synthesis, 27 attempted, and only 2 の 27 attempted compounds were synthesizable.
The MRSA track ran 29,014,974 generated molecules to 90 shortlisted, 22 procured, そして 6 active at 64 μg/mL, which the authors report as the MRSA track’s 27.3% true discovery rate. The lead compound matters biologically: NG1 binds LptA, an outer-membrane construction protein that existing antibiotics do not target, そしてその 0.5 μg/mL MIC against N. gonorrhoeae came with roughly a 3-log CFU reduction in a mouse vaginal model. Both pathogens sit on the 2024 WHO priority list as high priority.
The enzyme story is a different kind of evidence. The report’s agents recovered 198,290 reverse-transcriptase clusters, scored 3,564 candidate partner protein families, and promoted 17 to human-readable reports. The report itself carries the “ART (hypothesis)” label and states that the findings await experimental characterization. Independent reporting notes the report has not been peer reviewed and that the same reverse transcriptase appeared in a 2021 jumbo-phage paper (Wired, 2026).
Why tens of millions of candidates collapse to a few dozen synthesized compounds
The cited campaigns show synthesis and experimental testing can constrain specific discovery efforts. They do not establish that prediction is adequate or that synthesis is the dominant bottleneck in every peptide program. Evaluate both.
Peptide programs meet the same wall from the other direction. A generative peptide campaign reported 86 の 100 designed peptides were active, but its generation was capped at sequences under 50 残留物, そして 1 の 20 benchmark peptides could not be synthesized at all (ApexGO, Nature Machine Intelligence, 2026). あ 100% synthesis success rate on a 20-peptide benchmark is not the same claim as 86% activity on 100 ペプチド, and neither number transfers to a hydrophobic 40-mer.
How synthesis feasibility becomes an input to candidate ranking
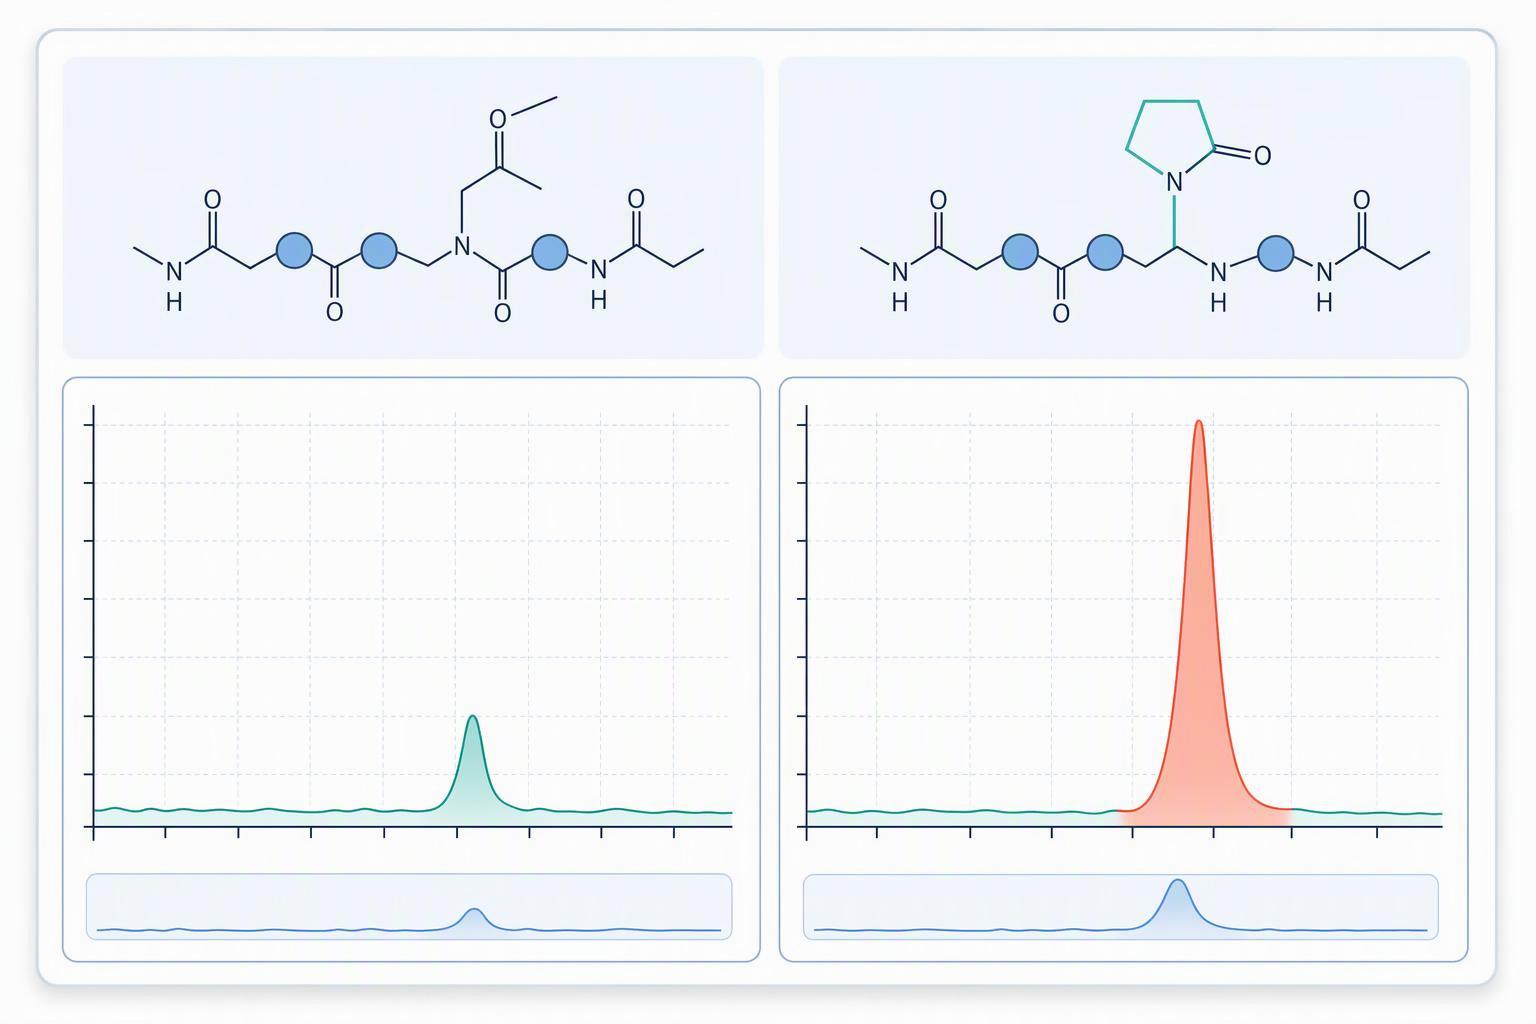
Feasibility belongs inside the scoring function, not in the queue after it. A model that ranks by predicted activity alone will keep handing the lab sequences the lab cannot make, and every failed coupling costs a cycle the campaign cannot get back. The cost is measurable. あ 2026 自然化学 study of 539 sequences found that pseudoproline substitution lifted crude purity from 23% に 69% for an hGH fragment and from 17% に 75% for a GB1 fragment, with aggregating sequences flagged by deprotection peak broadening above 20% relative to the first coupling (タマスら。, 自然化学, 2026).
The same work shows what to score. Aggregation-promoting residue composition, not the exact sequence, carried most of the predictive signal: であること(t-Bu), と, Val and Thr(t-Bu) raised the likelihood most, グレン(トルト) and Leu contributed heavily, the Gly–Ser and Leu–Leu motifs mattered, and aggregation typically set in 5 に 15 residues from the resin anchor.
チップ用: Five feasibility inputs to add to the ranking function: aggregation-prone composition, motif flags, length against the synthesizer’s validated range, modification complexity, and purification risk. A sequence that scores well on activity and badly on all five is a queue item, not a candidate.
One integration question remains open. The ApexGO optimizer described in the MIT work does not appear to model aggregation propensity, so a design-to-synthesis workflow still needs that layer added between model output and the synthesis queue.
What “validated” means for an AI-nominated peptide
Validate each method for its intended attribute. HPLC purity and an MS identity result answer complementary questions, but merely pairing them does not prove orthogonal confirmation of every structural feature or validate quantitative potency and content.
|
属性 |
質問に答える |
Primary method |
Orthogonal partner |
標準 |
Common CoA omission |
|---|---|---|---|---|---|
|
身元 |
Is this the sequence Synthetic Peptide Supplier ordered? |
LC-MS |
Amino acid analysis or MS/MS sequencing |
I Q6B |
Mass reported without interpretation |
|
純度 |
How much target peptide is present? |
RP- Purepeptides HPLC |
HPLC on a different chemistry |
I Q2(R2) |
Area percent only, no method detail |
|
効力 |
Does it perform in the assay? |
Functional assay |
Orthogonal bioassay |
I Q6B Peptide Source |
Not reported for research lots |
|
コンテンツ |
How much peptide is in the vial? |
定量分析 |
Mass balance |
I Q6B |
Net peptide content absent |
|
エンドトキシン |
Is the material safe for the assay system? |
LAL test |
Method-suitability controls |
米国薬局 <85> |
Limit not stated |
For cell-based assays, justify endotoxin control from assay sensitivity, concentration and interference. Parenteral K/M limits are not default cell-assay criteria. エンドトキシン, viable microorganisms and particles are different attributes and need suitable controls where relevant.
What makes peptide material assay-ready, and how to rule out artifacts
Assay-ready peptide material is material whose behaviour in the assay has been separated from the assay’s own interference. The standard aggregation counterscreen exists because peptides aggregate at low-to-mid micromolar concentrations, forming particles 100 に 500 nm across that bind protein in the picomolar range and are invisible to the eye (Auld, Inglese & Dahlin, Assay Guidance Manual, 2017).
Select aggregation, membrane-damage, adsorption and vehicle controls for the actual assay. Literature concentrations or LDH response ranges are not universal acceptance limits, and detergent may itself alter a membrane-active peptide’s mechanism.
What governance separates computational promise from validated performance
Governance separates the two by keeping the model’s output and the measured result in separate, versioned records, and by refusing to let one stand in for the other. The Part 11 audit-trail language defines an electronic record as any combination of text, graphics, データ, audio, pictorial or other information representation created, 修正された, 維持された, アーカイブされた, retrieved or distributed by a computer system, and makes computer systems and their documentation subject to FDA inspection (21 CFRパート 11, eCFR).
That governs records, not model validity. Nothing in the regulation says a generative model is qualified because its outputs are logged. The enzyme campaign shows why the distinction matters: the report’s own statement that the function is unknown sits beside ten reruns that never resurfaced the array as the discovery.
|
Claim |
Status |
What would move it forward |
|---|---|---|
|
36 million compounds generated |
Demonstrated, peer reviewed |
Nothing further |
|
6 の 22 MRSA compounds active in vitro Peptide Test Manufacturer |
Demonstrated, peer reviewed |
Independent replication |
|
NG1 efficacy in a mouse model |
Demonstrated in animals only |
No clinical claim permitted |
|
ART system function |
Hypothesis, not peer reviewed |
Experimental characterization |
|
Model ranking predicts synthesis success |
Not established |
Prospective synthesis data |
What a peptide program should change now
Change the ranking function first, then the analytical package, then the records. Concretely: add feasibility scoring before the shortlist, require an orthogonal identity method on every lot, run aggregation counterscreens before believing primary actives, and keep model output and measured results in separate versioned records with an audit trail.
Where synthesis is the constraint, the supplier conversation matters more than the model. Our team at MOL Changes runs Fmoc solid-phase synthesis with reverse-phase HPLC and mass spectrometry data supplied with every custom peptide order, covers N-terminal, C-terminal and side-chain modifications including cyclisation, disulfide bridges, non-natural amino acids and stable isotope incorporation, and scales from milligrams to kilograms through lyophilisation. Facilities use dual isolation, HEPA filtration and positive-pressure space, with in-process testing of purity, コンテンツ, エンドトキシン, pH and sterility under a self-inspection regime.
|
Window |
Action |
|---|---|
|
30 日 |
Add the five feasibility inputs to the ranking function; audit the last three CoAs for missing identity or content data |
|
60 日 |
Pair every purity method with an orthogonal identity method; add aggregation counterscreen to the standard assay protocol |
|
90 日 |
Separate model-output records from measured-result records with versioning and audit trail; write the claim-status register for every active program |
よくある質問
しますか? 86% peptide hit rate prove AI peptide design beats small-molecule campaigns?
いいえ. の 86 の 100 designed peptides were active against at least one of 11 pathogens, while the Cell paper’s 27.3% is activity among 22 synthesized small molecules. Different denominators, different chemical space, different starting points.
Why do so many AI-generated candidates fail at synthesis?
Because generation is not constrained by synthesis routes. の Cell authors report that only 2 の 27 attempted compounds in one track were synthesizable, and that one fragment had to be truncated because none of its top five compounds were accessible within typical timeframes and costs.
Is the enzyme discovery peer reviewed?
いいえ. The technical report has not been peer reviewed, labels the system a hypothesis, and states the findings await experimental characterization.
Do ICH and USP standards apply to research-grade peptides?
I Q2(R2) and Q6B govern analytical validation and specification setting for medicinal products. For research-grade material, use them as the method-quality benchmark: orthogonal identity, demonstrated specificity, and stated endotoxin limits still tell you whether the CoA means anything.
How should peptide synthesis feasibility prioritization change a ranking function?
Score aggregation-prone composition, motif flags, length against the validated synthesis range, modification complexity and purification risk alongside predicted activity, and treat a high-activity, high-risk sequence as a queue item rather than a candidate.
結論
The MIT antibiotic campaign and the enzyme search show that a design-to-data loop can search enormous spaces and return prioritized hypotheses; they do not show that any compound or peptide is a drug. の Cell work stops at mouse infection models, the peptide campaign stops at in vitro MICs, and the enzyme system remains a hypothesis awaiting experiments. For AI-designed antibiotics and peptide research workflows, the weak links are synthesis feasibility, orthogonal validation and record governance, and each of those is an engineering problem a program can fix this quarter.
The shift we expect to see across the field is threefold: feasibility-aware design that ranks candidates by whether they can be made, orthogonal-by-default analytics that assume any single method can mislead, and claim labels that travel with the data so a mouse-model result is never read as a clinical one. Programs that adopt all three will convert AI candidate lists into assay-ready peptide material faster than programs that treat validation as a downstream formality.
A practical first step is to bring one difficult sequence and its intended assay to a technical conversation. Ask what the analytical package would need to contain before you would sign the CoA, and request a sample CoA and analytical package so the answer is a document rather than a promise. Nothing here is clinical or regulatory advice; decisions about candidate progression belong with your own scientific and medical reviewers.
Publisher disclosure: MOL Changes supplies peptide services and has a commercial interest in this topic. Service ranges and capability statements are supplier claims; availability and performance for a specific construct require project-specific evidence.