Varför $300 Million Benchmark reframes AI i Peptide Discovery and Development
GenScript i september 2026 aktieplacering satt ungefär $300 miljoner bakom ett enda krav: att flaskhalsen i AI vid upptäckt och utveckling av peptider sitter längst fram i pipelinen, inte baksidan. Bolaget utfärdade 77,126,000 nya aktier för HK$30,50 vardera till minst sex oberoende investerare, samlade in cirka 2,33 miljarder HKD netto (villkoren för placeringen, 2026-09-17). Det ofta upprepade "300 miljoner dollar" är en avrundad karaktärisering av höjningen snarare än en siffra från själva ansökan.
Var pengarna landar är viktigare än rubriken. Finansieringsfördelningen riktar cirka 1,63 miljarder HKD till AI-driven läkemedelsupptäcktsplattformskapacitet och infrastruktur, ungefär 470 miljoner HKD till R&D, digital arbetsflödesintegration och global expansion, och cirka 230 miljoner HKD till allmänna företagsändamål (2026-09-17). Det angivna automatiseringsmålet är ett "Gen-to-Protein"-arbetsflöde som går från AI-genererad sekvens till biologisk konstruktion till experimentell validering, byggd kring en "4-Day AI-to-Biology Validation Engine" och ett mål som handlar om 60% av den globala produktionskapaciteten vara AI-automationsdriven i slutet av 2026. De Tamarind Bio tie-up beskrivs som att koppla AI molekylär design med snabb labbvalidering (2026-08-05).
En inköpsanteckning före analysen: placerings- och allokeringssiffrorna spåras till ett enda uppströmsplaceringsmeddelande som återrapporterats över finansiella butiker, så de är en källa, inte fyra oberoende bekräftelser. Resten av den här artikeln granskar handoff-punkterna där en finansierad förutsägelse antingen blir material av analyskvalitet eller inte.
Key Takeaway: Kapitalet riktas mot segmentet före experimentell validering, vilket innebär att riktmärket att bedöma inte är modellprestanda utan vad som överlever syntes, rening och identitetsbekräftelse.
Den konventionella utsikten: AI har redan komprimerat tidslinjer för upptäckt av peptider
Mainstream-positionen är den generativa designen, multiparameteroptimering, och högpresterande datorer har redan kollapsat tidslinjen design-to-kandidat, och att leverantörsplattformar nu levererar end-to-end upptäckt av AI-peptidläkemedel. GenScript säger att dess "Gene-to-Protein"-arbetsflöde byggs mot detta syfte, vid sidan av det angivna automatiseringsmålet det ungefär 60% av sin globala produktionskapacitet vara AI-automationsdriven i slutet av 2026. Tamarind Bio-bindningen presenteras som en sammankoppling av AI-molekylär design med snabb labbvalidering, och det federerade lärarrangemanget under Lilly TuneLab har medlemsbiotekniker som bidrar med experimentella resultat för att förbättra modeller som förutsäger utvecklingsbarhet och ADMET-egenskaper.
Utsikten är populär eftersom den är riktriktad och kommersiellt läsbar. Ett decennium av verkliga vinster i strukturförutsägelse och fastighetsmodellering gav påståendet dess grund, och leverantörer marknadsför nu hela kedjan som en produkt. Säljarens egen plattformsjämförelse rapporterar en större än 95% framgångsfrekvens för syntes mot en 75% branschgenomsnitt, med sekvenser upp till 200 aminosyror mot en angiven 4 till 50 aminosyramarknadens genomsnitt. Dessa siffror är leverantörsangivna, inte oberoende verifierad.
Där den konventionella utsikten bryter: Tre handoff-poäng
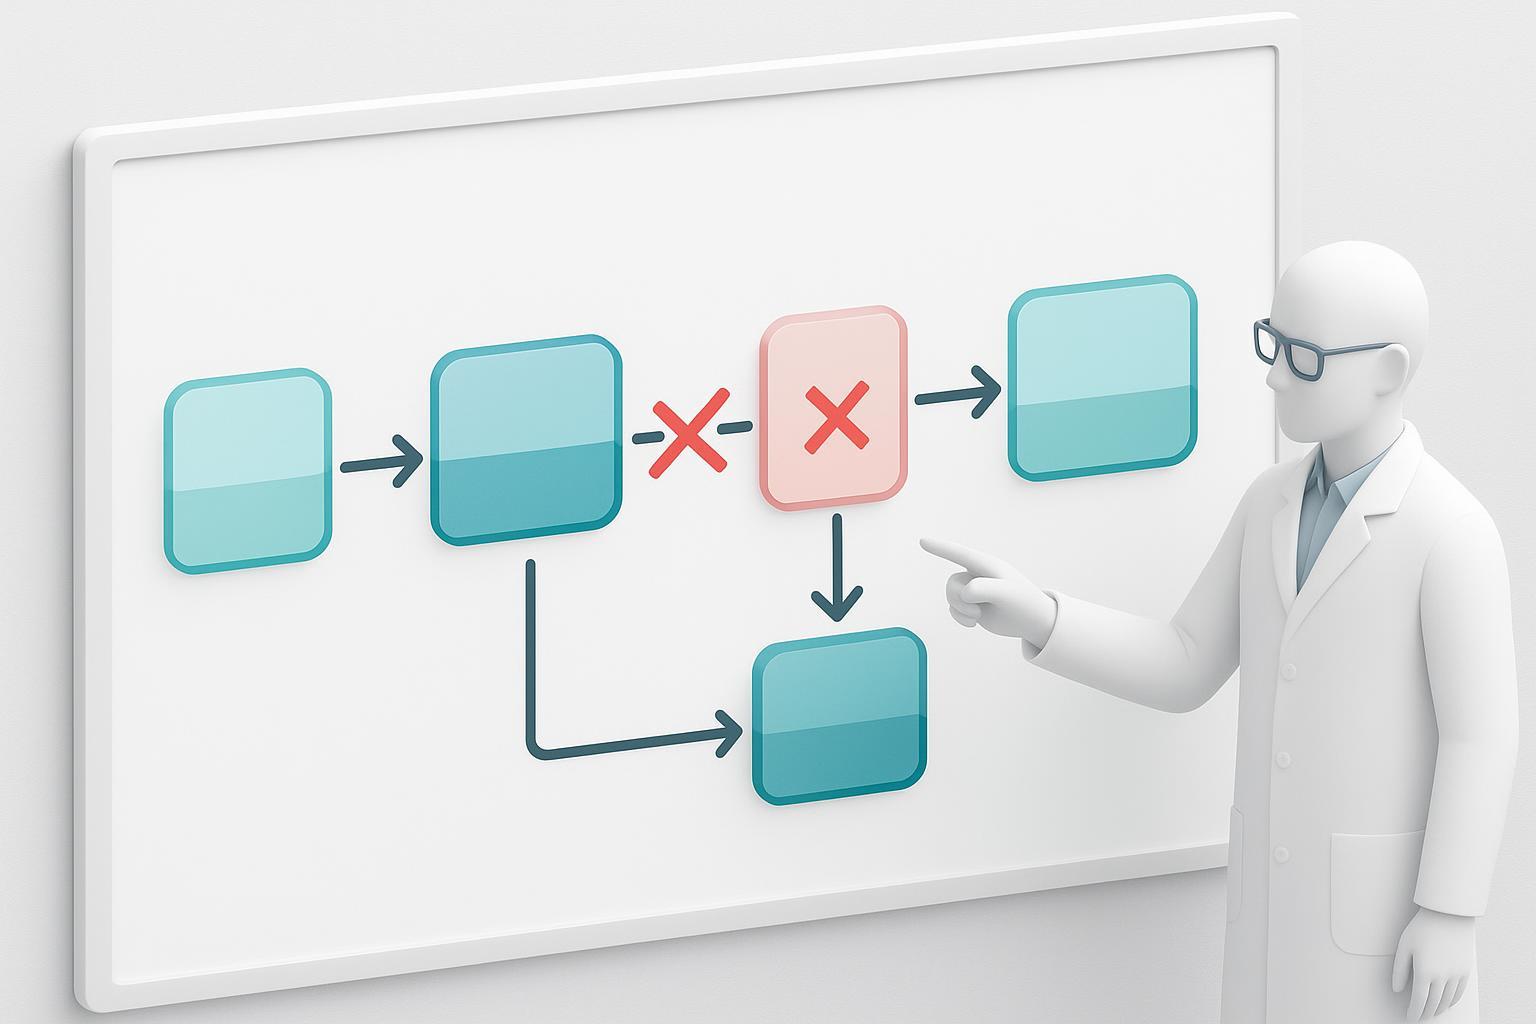
Rörledningen är inte kontinuerlig, och dess diskontinuiteter är där kandidater dör. En modellpoäng, en synteskörning, och en analysavläsning är tre separata system med tre separata fellägen, och den konventionella vyn kollapsar dem till en jämn linje från sekvens till resultat.
Det första avbrottet är inflationen i utvärderingsprotokollet. Rapporterade mätvärden citeras ofta utan att skilja en slumpmässigt uppdelad testuppsättning från en strukturellt olik en, so a headline number can read as validated performance when it reflects only how well a model interpolates within familiar sequence space. The recent review of data-driven peptide design makes this critique directly: reported discrimination scores can fall materially once the test set is split by scaffold rather than at random, which is the split that resembles a genuinely novel candidate.
The second break is synthesis feasibility, which is not a model output. When AI-nominated sequences reach the resin, the CDMO handoff checklist names the failure modes that follow: incomplete Fmoc deprotection, coupling attenuation and steric hindrance from on-resin aggregation, N-1 and N-2 deletion sequences from failed couplings, low crude purity, and low recovery. Length compounds the problem. GenScript’s own guidance states that peptides longer than 100 amino acids are “extremely difficult to synthesize” and are handled case by case through fragmentation and ligation, per the vendor’s own synthesis guidance.
The third break is assay artifact. Sub-micron colloidal aggregates can adsorb non-specifically to plates and sensor chips, producing artificial nanomolar signals that vanish against a monodisperse control.
Peptide synthesis quality control is where these breaks surface. All three share one root cause: the conventional view treats a prediction as a result.
⚠️ Varning: A model-reported metric is not validated performance until it survives a split that reflects real sequence novelty.
Vad data faktiskt visar om AI-designade peptider
The same numbers that get quoted as proof of AI-driven design success support a narrower claim: AI is a triage and prioritization layer whose output is a hypothesis, not a result. Read the evaluation conditions and the ceiling becomes visible.
The sequence-only developability benchmark reports 91.09% hemolysis, 86.30% non-fouling, och 75.56% solubility accuracy under similarity-controlled splits (the sequence-only developability benchmark, 2023-11). PeptideBERT’s reported accuracies land in a compatible range on overlapping endpoints, ungefär 86.05% hemolysis, 88.37% non-fouling, och 70.02% löslighet, which is partial independent corroboration rather than an echo (PeptideBERT preprint, 2023-09). Solubility is the weakest endpoint in both.
The CamSol-PTM solubility work shows why that matters for peptide developability screening: average Pearson correlation of 0.72 on non-natural-amino-acid peptides, falling to 0.58 on GLP-1 variants and 0.60 on the generalisation set, with two designs excluded as non-producible (CamSol-PTM, Nature Communications, 2023-11). A model can rank solubility well and still nominate sequences that cannot be made.
A three-gate sequence replaces the single confidence score: computational triage, then a synthesis feasibility screen, then analytical release. A candidate advances only on experimental evidence at each gate, which is what AI-designed peptides validation should mean in practice.
Det bättre tillvägagångssättet: Granska releasedata, Inte modellmåtten
Evaluate AI-enabled peptide vendors on their analytical release documentation, not on the model performance they report. The principle behind that shift is simple: a prediction is only as good as the material a supplier can hand you with a traceable analytical record behind it. Four requirements follow from the handoff points above.
-
Ask for the evaluation condition behind every performance claim. A random split and a structurally dissimilar test set produce very different numbers, and only one of them tells you how the model behaves on chemistry it has not seen.
-
Require orthogonal identity confirmation, not a single mass check. The proposed orthogonal validation suite pairs RP-HPLC on C18 and C4 with ESI-MS or MALDI-TOF, adds circular dichroism across far-UV 190 till 260 nm, DLS or SEC-MALS with a polydispersity index below 0.15, and an Ellman’s assay for free thiol under 0.05 mol SH/mol peptid. These are publisher-proposed criteria, not a standards-body mandate, so treat them as a starting specification to negotiate.
-
Require lot-to-lot traceability and a stated convention. The mass-balance convention that sums target peptide, peptidic impurities, counter ion and water to 100% is what makes a purity figure comparable between lots.
-
Peptidsyntes Require scale-up evidence from mg to kg, not a single-scale demonstration. The published scale ranges describe vendor specifications rather than independent benchmarks, so ask which scale the release data actually came from.
För tips: Ask for the split protocol before you ask for the performance number. A vendor who can describe the test set can usually describe the assay data too.
Suppliers such as MOL Changes publish analytical release documentation of this kind, which makes the audit a document request rather than a capability guess. This is where peptide synthesis quality control stops being a marketing claim and becomes a set of files you can read.
Hur man applicerar detta: A Buyer’s Evaluation Sequence
Request the analytical release package before you sit through the capability deck. That single reversal changes the conversation from what a model can predict to what a supplier can prove, and it is the fastest way to sort vendors who have validated material from vendors who have validated slides.
-
Ask for the evaluation protocol behind any reported model metric. Request the train/test split methodology, the held-out set composition, and whether the reported figure comes from retrospective scoring or prospective synthesis. Same-day ask, and the answer tells you whether the number is a benchmark or a marketing asset.
-
Submit a known-difficult sequence as a feasibility probe. A hydrophobic or aggregation-prone stretch reveals more than a catalog peptide ever will. Peptides over 100 amino acids are handled case by case under the vendor’s own synthesis guidance, so pick a probe near that boundary rather than inside the comfortable range. Days to weeks.
-
Audit the analytical package against orthogonal confirmation, not a single LC-MS trace. One mass spectrum confirms mass, not sequence. Ask how the supplier applies the proposed orthogonal validation suite and which methods are routine versus quoted separately.
-
Request lot-to-lot data and the mass-balance convention used to report net peptide content. This is where the mass-balance convention matters: Syntetiska peptider purity expressed against peptide mass and purity expressed against total dry weight are different claims, and only one of them survives scale-up.
-
Confirm scale-up evidence from milligram through kilogram with purity held at specification. The published scale ranges show what a supplier advertises; the lot history shows what it repeats.
Steg
Artifact requested
Vad den slår fast
Typical effort
1
Evaluation protocol and split methodology
Whether the metric is prospective or retrospective
Same day
2
Feasibility probe on a difficult sequence
Whether design claims survive synthesis
Days to weeks
3
Orthogonal confirmation package
Sequence identity beyond a single trace
Days
Lot-to-lot data and mass-balance convention
Whether purity claims are comparable across lots
Veckor
5
Scale-up evidence, mg to kg
Whether specification holds as batch size grows
Longer term
Track whether purity and identity hold across lots, not whether the first lot passed. A vendor without a feasibility probe or lot history is not disqualified, but it is unverified, and you should price that uncertainty into the decision.
Där detta argument är svagast
The analytical-release standard proposed here is not a regulatory requirement, and a vendor that meets it is not thereby a better scientific partner. It is a buyer-side diligence frame, assembled from published practice rather than from any binding guidance. The orthogonal validation suite described in the previous section is publisher-proposed, and no regulator compels a sponsor to run it before quoting a design platform’s output.
That distinction matters most in early exploratory work. If the goal is ranking hypotheses for a research team to triage, model metrics may be entirely sufficient, and demanding a full release audit at that stage is disproportionate to what the work is for. The audit earns its cost when a prediction is about to become assay-grade material.
One honest limitation: the evaluation-protocol critique rests partly on benchmark figures that could not be re-verified in this research round. If those figures degrade less under strict splits than reported, the critique weakens, though the handoff points it describes remain observable in published synthesis and purification practice.
The position is that predictions should be audited, not dismissed. Sequencing evidence is the argument, not rejecting computational methods.
But Doesn’t Faster Design Still Create Real Value?
Ja, and nothing in this argument disputes it. Compressing a search space and deciding which sequences are worth making is real work with real savings, and that is where AI in peptide discovery and development has earned its place.
The clearest published example is the AlphaFold-screened active-learning study, which reports recovering 50% of all binders using 15% of the queries that exhaustive sampling would require, a 3.3× improvement over random sampling. That is a substantial gain in query efficiency, and it is worth being precise about what it measures: how many candidates a model must evaluate to surface a shortlist. The result is a preprint and has not been peer reviewed, so treat the magnitude as provisional rather than settled.
The disagreement is narrower than it looks. Query efficiency is a design-stage gain. It tells you which sequences to order. It says nothing about whether the binders you recover can be synthesized at specification, purified to an acceptable impurity profile, or confirmed by an orthogonal method. A shortlist that cannot clear those steps is a faster route to a failed lot.
Vad händer om vi redan har investerat i en AI-designplattform?
The investment is not wasted, and the transition is additive rather than a restart. A design platform keeps doing what it does well: ranking candidates, flagging liabilities, and narrowing a large sequence space to a shortlist worth making. What changes is that the organization adds a feasibility and release gate downstream, where each shortlisted candidate is judged on synthesizability, purification behavior, and orthogonal identity confirmation before it consumes assay capacity. The two layers are complementary, not competing.
The practical sequencing is straightforward. Keep the model. Add the probe. Then require the full analytical package on the first three candidates before scaling the relationship to routine work. That last step matters because it converts a vendor relationship into a documented one: you learn how the platform’s predictions behave against your own release criteria, on your own sequences, rather than against a benchmark set.
Where a transition metric would help, note that figures of this type vary by source, so treat any single number with caution. The federated-learning arrangement is a useful illustration of the underlying principle: design outputs and experimental results improve each other when they are connected in a loop rather than kept in separate systems.
Hur svarar du på leverantörer som citerar starka publicerade riktmärken?
Engage the benchmark’s methodology rather than disputing its number. A high score under a random train-test split and a lower score under a scaffold or single-linkage split are both correct measurements of different things, and the useful question is which measurement the vendor’s claim actually describes. That is a question about scope, not about honesty.
The recent review of data-driven peptide design makes this concrete: random splits let near-duplicate analogs sit on both sides of the partition, so a model can score well by recognizing close relatives of its training set rather than by generalizing to a new chemical series. Scaffold and single-linkage splits remove that shortcut and produce lower, more honest numbers.
The CamSol-PTM solubility work shows the same effect at the endpoint level. Its reported performance averages around 0.72 across the benchmark, but drops to roughly 0.58 on GLP-1 variants, a narrower and harder scope. Both figures are real. Neither is the whole story.
For AI-designed peptides validation, the practical move is to ask which split, which endpoint, and which chemical scope produced the number. Vendors who publish their split methodology are easier to evaluate, not harder, because the claim arrives with its boundaries attached.
Den förändring som industrin behöver
The benchmark GenScript’s $300 million raise sets should be measured in analytical release capability, not model metrics. That is the argument this piece has built toward, and it follows directly from management’s own framing of the raise: the capital expands the part before experimental validation, while synthesis execution, analytisk rigor, and sterile manufacturing capability remain unchanged by it.
What needs to change is a market norm, not a single vendor’s practice. AI-enabled peptide suppliers should publish evaluation conditions alongside performance claims, and release orthogonal analytical data alongside capability decks, following something like the proposed orthogonal validation suite rather than a headline accuracy figure. Buyers should ask for both before treating a design claim as a deliverable.
The vision is modest but useful: “AI-designed” becomes a statement about where a sequence came from, and the release package decides whether it is usable. The next step is concrete. Request the analytical documentation and validation package for a candidate you are evaluating, and judge the vendor on what that package actually shows about AI in peptide discovery and development.
Disclosure: MOL Changes operates in the peptide CDMO market discussed here, so this analysis carries a commercial interest. Nothing in this article is medical or clinical advice; consult a qualified professional before making decisions with biological or clinical implications.